EfficientNetB3 training
EfficientNetB3_train.ipynb: 39 cells (21 of code), 2 pictures, Python 3.11.9
# Google Colab specific imports
from google.colab import drive
# Core libraries
import numpy as np
import pandas as pd
import os
import time
import shutil

# Suppress TensorFlow warnings
os.environ['TF_CPP_MIN_LOG_LEVEL'] = '2'

# Visualization
import matplotlib.pyplot as plt
import cv2
from PIL import Image
import seaborn as sns
sns.set_style('darkgrid')

# Machine Learning
from sklearn.metrics import confusion_matrix, classification_report
from sklearn.model_selection import train_test_split

# TensorFlow and Keras
import tensorflow as tf
from tensorflow import keras

# Enable mixed precision for faster training on GPU
from tensorflow.keras import mixed_precision
policy = mixed_precision.Policy('float32')
mixed_precision.set_global_policy(policy)
print('Compute dtype: %s' % policy.compute_dtype)
print('Variable dtype: %s' % policy.variable_dtype)
# Keras modules
from tensorflow.keras.preprocessing.image import ImageDataGenerator
from tensorflow.keras.layers import Dense, Activation, Dropout, Conv2D, MaxPooling2D, BatchNormalization
from tensorflow.keras.optimizers import Adam, Adamax
from tensorflow.keras.metrics import categorical_crossentropy
from tensorflow.keras import regularizers
from tensorflow.keras.models import Model

# Check GPU availability
print("GPU Available:", tf.config.list_physical_devices('GPU'))
if tf.config.list_physical_devices('GPU'):
    print("GPU detected! Training will be fast.")
else:
    print("No GPU detected. Training will be slow.")
Out
Compute dtype: float32
Variable dtype: float32
GPU Available: [PhysicalDevice(name='/physical_device:GPU:0', device_type='GPU')]
GPU detected! Training will be fast.
# Install Albumentations (run once in the notebook environment)
# If running locally, you can comment out the pip install line and install via your environment
%pip install albumentations==1.1.0 -q

import albumentations as A
import numpy as np

# Define richer training augmentations to better simulate real-world clutter
train_augment = A.Compose([
    A.RandomRotate90(p=0.5),
    A.HorizontalFlip(p=0.5),
    A.ShiftScaleRotate(shift_limit=0.08, scale_limit=0.08, rotate_limit=20, p=0.7),
    A.RandomBrightnessContrast(brightness_limit=0.2, contrast_limit=0.2, p=0.7),
    A.GaussianBlur(blur_limit=3, p=0.2),
    A.GaussNoise(var_limit=(10.0, 50.0), p=0.2),
    A.GridDropout(ratio=0.2, p=0.3),
    A.CoarseDropout(max_holes=1, max_height=50, max_width=50, p=0.3),
], p=1.0)

# Preprocessing function for ImageDataGenerator: apply Albumentations then EfficientNet preprocess
def albumentations_preprocess(image):
    # ImageDataGenerator passes images as float32 arrays in [0,255]
    img_uint8 = image.astype('uint8')
    augmented = train_augment(image=img_uint8)['image']
    # Convert to float32 and apply EfficientNet preprocessing
    return tf.keras.applications.efficientnet.preprocess_input(augmented.astype('float32'))
Out
/usr/local/lib/python3.12/dist-packages/albumentations/augmentations/transforms.py:1952: UserWarning: blur_limit and sigma_limit minimum value can not be both equal to 0. blur_limit minimum value changed to 3.
  warnings.warn(
The size of the images are very large. If you try to use the full image size training will take a very long time. Therefore you
want to reduce the image size. However if you include resizing of images as part of training it requires each image to be repeatedly
resized in each epoch. This also make the training times to be large. It is more efficient to resize all the images FIRST and save them.
Then use these images for training.
Resize all images and save to the working directory
# Mount Google Drive
drive.mount('/content/drive')
start_time=time.time()
sdir = '/content/drive/MyDrive/dataset_train'
working_dir = '/content/cauliflower_training/'
img_height = 300
img_width = 300

# Create working directory first
os.makedirs(working_dir, exist_ok=True)

save_path = os.path.join(working_dir, 'cali')

if os.path.isdir(save_path):
    shutil.rmtree(save_path) # if the directory exists remove it

os.makedirs(save_path, exist_ok=True)  # Changed from os.mkdir() to os.makedirs()

classlist = sorted(os.listdir(sdir))
for klass in classlist:
    classpath = os.path.join(sdir, klass)
    if not os.path.isdir(classpath):  # skip if not a directory
        continue
    print('processing ', klass,  ' class')
    class_dest_path = os.path.join(save_path, klass)
    os.makedirs(class_dest_path, exist_ok=True)  # Changed here too
    flist = os.listdir(classpath)
    for f in flist:
        fpath = os.path.join(classpath,f)
        f_dest_path = os.path.join(class_dest_path, f)
        try: # make sure images are correct image files
            # Use PIL to ensure consistent RGB handling across readers
            with Image.open(fpath) as img:
                img = img.convert('RGB')
                # Use modern resampling API when available
                try:
                    resample_method = Image.Resampling.LANCZOS
                except AttributeError:
                    resample_method = Image.LANCZOS if hasattr(Image, 'LANCZOS') else Image.NEAREST
                img = img.resize((img_height, img_width), resample_method)
                img.save(f_dest_path)
        except Exception as e:
            print('Image ', fpath, ' is an invalid image file:', e)

tr_duration = time.time() - start_time
hours = tr_duration // 3600
minutes = (tr_duration - (hours * 3600)) // 60
seconds = tr_duration - ((hours * 3600) + (minutes * 60))
msg = f'resizing elapsed time was {str(hours)} hours, {minutes:4.1f} minutes, {seconds:4.2f} seconds)'
print(msg, flush=True)
Out
Drive already mounted at /content/drive; to attempt to forcibly remount, call drive.mount("/content/drive", force_remount=True).
processing  Alternaria Leaf Spot  class
processing  Bacterial Soft Rot  class
processing  Black Rot  class
processing  Downy Mildew  class
processing  Healthy  class
resizing elapsed time was 0.0 hours, 6.0 minutes, 15.52 seconds)from PIL import Image
import shutil
import os
sdir = '/content/drive/MyDrive/dataset_train'
quarantine = os.path.join(working_dir, 'quarantine')
os.makedirs(quarantine, exist_ok=True)
moved = 0
for root, _, files in os.walk(sdir):
for f in files:
path = os.path.join(root, f)
# skip if already in quarantine
try:
if os.path.commonpath([quarantine, path]) == quarantine:
continue
except ValueError:
# fallback when commonpath can't compare (different path types/drives)
abs_quarantine = os.path.abspath(quarantine)
abs_path = os.path.abspath(path)
if abs_path == abs_quarantine or abs_path.startswith(abs_quarantine + os.sep):
continue
try:
with Image.open(path) as im:
im.verify() # will raise if file is truncated or not an image
except Exception:
rel = os.path.relpath(path, sdir)
dest_path = os.path.join(quarantine, rel)
os.makedirs(os.path.dirname(dest_path), exist_ok=True)
try:
shutil.move(path, dest_path)
moved += 1
except Exception as e:
print('Failed to move', path, '->', dest_path, ':', e)
print(f'Moved {moved} files to quarantine: {quarantine}')Out
Moved 0 files to quarantine: /content/cauliflower_training/quarantine
Read in resized images and create a dataframe of image paths and class labels
def make_df(save_path):
    classlist=os.listdir(save_path)
    filepaths=[]
    labels=[]
    for klass in classlist:
        classpath=os.path.join(save_path, klass)
        flist=os.listdir(classpath)
        for f in flist:
            fpath=os.path.join(classpath,f)
            filepaths.append(fpath)
            labels.append(klass)
    Fseries=pd.Series(filepaths, name='filepaths')
    Lseries=pd.Series(labels, name='labels')
    df=pd.concat([Fseries, Lseries], axis=1)
    train_df, dummy_df=train_test_split(df, train_size=.8, shuffle=True, random_state=123, stratify=df['labels'])
    valid_df, test_df=train_test_split(dummy_df,train_size=.5, shuffle=True, random_state=123, stratify=dummy_df['labels'])
    print('train_df lenght: ', len(train_df), '  test_df length: ', len(test_df), '  valid_df length: ', len(valid_df))
    # get the number of classes and the images count for each class in train_df
    classes=sorted(list(train_df['labels'].unique()))
    class_count = len(classes)
    print('The number of classes in the dataset is: ', class_count)
    groups=train_df.groupby('labels')
    print('{0:^30s} {1:^13s}'.format('CLASS', 'IMAGE COUNT'))
    countlist=[]
    classlist=[]
    for label in sorted(list(train_df['labels'].unique())):
        group=groups.get_group(label)
        countlist.append(len(group))
        classlist.append(label)
        print('{0:^30s} {1:^13s}'.format(label, str(len(group))))

    # get the classes with the minimum and maximum number of train images
    max_value=np.max(countlist)
    max_index=countlist.index(max_value)
    max_class=classlist[max_index]
    min_value=np.min(countlist)
    min_index=countlist.index(min_value)
    min_class=classlist[min_index]
    print(max_class, ' has the most images= ',max_value, ' ', min_class, ' has the least images= ', min_value)
    # lets get the average height and width of a sample of the train images
    ht=0
    wt=0
    # select 100 random samples of train_df
    train_df_sample=train_df.sample(n=100, random_state=123,axis=0)
    for i in range (len(train_df_sample)):
        fpath=train_df_sample['filepaths'].iloc[i]
        img=plt.imread(fpath)
        shape=img.shape
        ht += shape[0]
        wt += shape[1]
    print('average height= ', ht//100, ' average width= ', wt//100, 'aspect ratio= ', ht/wt)
    return train_df, test_df, valid_df, classes
train_df, test_df, valid_df, classes = make_df(save_path)
class_count=len(classes)
Out
train_df lenght:  6203   test_df length:  776   valid_df length:  775
The number of classes in the dataset is:  5
            CLASS               IMAGE COUNT
     Alternaria Leaf Spot          1206
      Bacterial Soft Rot           1121
          Black Rot                 627
         Downy Mildew               721
           Healthy                 2528
Healthy  has the most images=  2528   Black Rot  has the least images=  627
average height=  300  average width=  300 aspect ratio=  1.0
Balancing Dataset
# IMPROVED BALANCE FUNCTION - Now handles both upsampling AND downsampling
def balance(df, n, working_dir, img_size):
    """
    Balance dataset to exactly n samples per class by:
    1. Downsampling majority classes to n
    2. Augmenting minority classes up to n
    """
    df = df.copy()
    print(f'Initial dataframe length: {len(df)}')
    print('\n=== Initial Class Distribution ===')
    initial_dist = df['labels'].value_counts().sort_index()
    print(initial_dist)

    # STEP 1: DOWNSAMPLE majority classes first
    print(f'\n=== Step 1: Downsampling classes with > {n} samples ===')
    balanced_frames = []
    for label in sorted(df['labels'].unique()):
        class_df = df[df['labels'] == label]
        count = len(class_df)

        if count > n:
            class_df = class_df.sample(n=n, random_state=123)
            print(f'✓ Downsampled {label:30s} from {count:4d} to {n}')
        else:
            print(f'  Kept {label:30s} at {count:4d} samples (will augment later)')

        balanced_frames.append(class_df)

    df = pd.concat(balanced_frames, axis=0).reset_index(drop=True)
    print(f'\nAfter downsampling: {len(df)} total samples')

    # STEP 2: AUGMENT minority classes
    print(f'\n=== Step 2: Augmenting classes with < {n} samples ===')
    aug_dir = os.path.join(working_dir, 'aug')
    if os.path.isdir(aug_dir):
        shutil.rmtree(aug_dir)
    os.mkdir(aug_dir)

    for label in df['labels'].unique():
        dir_path = os.path.join(aug_dir, label)
        os.mkdir(dir_path)

    total_augmented = 0
    gen = ImageDataGenerator(
        horizontal_flip=True,
        rotation_range=20,
        width_shift_range=.2,
        height_shift_range=.2,
        zoom_range=.2
    )

    groups = df.groupby('labels')
    for label in sorted(df['labels'].unique()):
        group = groups.get_group(label)
        sample_count = len(group)

        if sample_count < n:
            delta = n - sample_count
            target_dir = os.path.join(aug_dir, label)
            print(f'✓ Creating {delta:3d} augmented images for {label:30s}')

            aug_gen = gen.flow_from_dataframe(
                group,
                x_col='filepaths',
                y_col=None,
                target_size=img_size,
                class_mode=None,
                batch_size=1,
                shuffle=False,
                save_to_dir=target_dir,
                save_prefix='aug-',
                color_mode='rgb',
                save_format='jpg'
            )

            aug_img_count = 0
            while aug_img_count < delta:
                images = next(aug_gen)
                aug_img_count += len(images)

            total_augmented += aug_img_count

    print(f'\nTotal augmented images created: {total_augmented}')

    # STEP 3: Merge augmented images
    aug_fpaths = []
    aug_labels = []
    classlist = os.listdir(aug_dir)
    for klass in classlist:
        classpath = os.path.join(aug_dir, klass)
        flist = os.listdir(classpath)
        for f in flist:
            fpath = os.path.join(classpath, f)
            aug_fpaths.append(fpath)
            aug_labels.append(klass)

    if aug_fpaths:
        Fseries = pd.Series(aug_fpaths, name='filepaths')
        Lseries = pd.Series(aug_labels, name='labels')
        aug_df = pd.concat([Fseries, Lseries], axis=1)
        df = pd.concat([df, aug_df], axis=0).reset_index(drop=True)

    print(f'\n=== Final Balanced Distribution ===')
    final_dist = df['labels'].value_counts().sort_index()
    print(final_dist)
    print(f'\nFinal dataframe length: {len(df)}')

    # Verify perfect balance
    if final_dist.nunique() == 1 and final_dist.iloc[0] == n:
        print(f'✓ SUCCESS: All classes perfectly balanced at {n} samples!')
    else:
        print('⚠ WARNING: Classes not perfectly balanced!')

    # Save to CSV
    try:
        merged_csv = os.path.join(working_dir, 'train_balanced.csv')
        df.to_csv(merged_csv, index=False)
        print(f'\n✓ Saved balanced dataset to: {merged_csv}')
    except Exception as e:
        print(f'Warning: could not save CSV: {e}')

    return df

# Apply balancing
n = 600  # Increased from 200 for better model training
working_dir = r'./'
img_size = (300, 300)

print('=' * 80)
print('BALANCING TRAINING DATASET')
print('=' * 80)
train_df = balance(train_df, n, working_dir, img_size)
Out
================================================================================
BALANCING TRAINING DATASET
================================================================================
Initial dataframe length: 6203

=== Initial Class Distribution ===
labels
Alternaria Leaf Spot    1206
Bacterial Soft Rot      1121
Black Rot                627
Downy Mildew             721
Healthy                 2528
Name: count, dtype: int64

=== Step 1: Downsampling classes with > 600 samples ===
✓ Downsampled Alternaria Leaf Spot           from 1206 to 600
✓ Downsampled Bacterial Soft Rot             from 1121 to 600
✓ Downsampled Black Rot                      from  627 to 600
✓ Downsampled Downy Mildew                   from  721 to 600
✓ Downsampled Healthy                        from 2528 to 600

After downsampling: 3000 total samples

=== Step 2: Augmenting classes with < 600 samples ===

Total augmented images created: 0

=== Final Balanced Distribution ===
labels
Alternaria Leaf Spot    600
Bacterial Soft Rot      600
Black Rot               600
Downy Mildew            600
Healthy                 600
Name: count, dtype: int64

Final dataframe length: 3000
✓ SUCCESS: All classes perfectly balanced at 600 samples!

✓ Saved balanced dataset to: ./train_balanced.csv
Rebuild cleaned CSVs
def write_clean_csv(input_csv, out_csv, quarantine_dir):
    df = pd.read_csv(input_csv)
    # drop any rows whose files were moved to quarantine
    if os.path.isdir(quarantine_dir):
        quarantined = set(os.listdir(quarantine_dir))
        df = df[~df['filepaths'].apply(lambda p: os.path.basename(p) in quarantined)].reset_index(drop=True)
    df.to_csv(out_csv, index=False)
    print('Wrote cleaned CSV:', out_csv)

# Define quarantine_dir (needed if you ran the repair cell earlier)
quarantine_dir = os.path.join(working_dir, 'quarantine')

# Only run if the input CSV exists
input_csv = os.path.join(working_dir, 'train_augmented.csv')
output_csv = os.path.join(working_dir, 'train_augmented_clean.csv')

if os.path.exists(input_csv):
    write_clean_csv(input_csv, output_csv, quarantine_dir)
else:
    print(f'Skipping CSV cleaning - {input_csv} not found yet (run balance function first)')
Out
Skipping CSV cleaning - ./train_augmented.csv not found yet (run balance function first)
Expand train_df by creating augmented images
# Load the balanced dataset (skip if already balanced in memory)
balanced_csv = os.path.join(working_dir, 'train_balanced.csv')

if os.path.exists(balanced_csv):
    print(f"Loading pre-balanced dataset: {balanced_csv}")
    train_df = pd.read_csv(balanced_csv)
    if 'filepaths' not in train_df.columns:
        cols = list(train_df.columns)
        if len(cols) >= 2:
            train_df = train_df.rename(columns={cols[0]: 'filepaths', cols[1]: 'labels'})
    train_df = train_df[['filepaths', 'labels']]

    print(f'\n✓ Loaded balanced dataset: {len(train_df)} samples')
    print('\nClass distribution:')
    print(train_df['labels'].value_counts().sort_index())
else:
    print(f"⚠ {balanced_csv} not found — ensure you ran the balance() function first")
Out
Loading pre-balanced dataset: ./train_balanced.csv

✓ Loaded balanced dataset: 3000 samples

Class distribution:
labels
Alternaria Leaf Spot    600
Bacterial Soft Rot      600
Black Rot               600
Downy Mildew            600
Healthy                 600
Name: count, dtype: int64
Create the train_gen, test_gen final_test_gen and valid_gen
batch_size = 128  # Reduced from 80 for better gradient updates with balanced data
AUTOTUNE = tf.data.AUTOTUNE

# Build class mapping
class_names = sorted(train_df['labels'].unique())
class_to_idx = {name: idx for idx, name in enumerate(class_names)}
class_count = len(class_names)

# Helper to build tf.data datasets from dataframe
def df_to_dataset(df, training=False):
    paths = df['filepaths'].astype(str).values
    labels = df['labels'].map(class_to_idx).values.astype('int32')
    ds = tf.data.Dataset.from_tensor_slices((paths, labels))
    if training:
        ds = ds.shuffle(buffer_size=1000, seed=123)
        ds = ds.map(lambda p, l: tf.py_function(func=_decode_and_preprocess_train, inp=[p, l], Tout=(tf.float32, tf.float32)), num_parallel_calls=AUTOTUNE)
    else:
        ds = ds.map(lambda p, l: tf.py_function(func=_decode_and_preprocess_eval, inp=[p, l], Tout=(tf.float32, tf.float32)), num_parallel_calls=AUTOTUNE)
    ds = ds.batch(batch_size).prefetch(AUTOTUNE)
    return ds

# Functions used by tf.py_function must accept and return numpy-compatible types
def _decode_and_preprocess_train(path, label):
    path = path.numpy().decode('utf-8')
    img = tf.io.read_file(path)
    img = tf.image.decode_jpeg(img, channels=3)
    img = tf.image.resize(img, img_size)
    img = tf.cast(img, tf.uint8).numpy()
    # Albumentations preprocessing returns float32 preprocessed image
    img_pp = albumentations_preprocess(img)
    label_ohe = tf.one_hot(int(label.numpy()), depth=class_count).numpy()
    return img_pp, label_ohe

def _decode_and_preprocess_eval(path, label):
    path = path.numpy().decode('utf-8')
    img = tf.io.read_file(path)
    img = tf.image.decode_jpeg(img, channels=3)
    img = tf.image.resize(img, img_size)
    img = tf.cast(img, tf.float32).numpy()
    img_pp = tf.keras.applications.efficientnet.preprocess_input(img)
    label_ohe = tf.one_hot(int(label.numpy()), depth=class_count).numpy()
    return img_pp, label_ohe

print('Creating tf.data datasets...')
train_ds = df_to_dataset(train_df, training=True)
valid_ds = df_to_dataset(valid_df, training=False)
test_ds = df_to_dataset(test_df, training=False)

train_steps = int(np.ceil(len(train_df) / batch_size))
valid_steps = int(np.ceil(len(valid_df) / batch_size))
test_steps = int(np.ceil(len(test_df) / batch_size))

print(f'\n✓ tf.data datasets created successfully')
print(f'  Train steps (batches): {train_steps}')
print(f'  Valid steps (batches): {valid_steps}')
print(f'  Test steps (batches): {test_steps}')
print(f'  Number of classes: {class_count}')
# expose variables expected later
classes = class_names
labels = test_df['labels'].map(class_to_idx).values
Out
Creating tf.data datasets...

✓ tf.data datasets created successfully
  Train steps (batches): 24
  Valid steps (batches): 7
  Test steps (batches): 7
  Number of classes: 5
def _py_train(path, label):
    img, lbl = tf.py_function(func=_decode_and_preprocess_train, inp=[path, label], Tout=(tf.float32, tf.float32))
    img.set_shape([img_size[0], img_size[1], 3])
    lbl.set_shape([class_count])
    return img, lbl


def _py_eval(path, label):
    img, lbl = tf.py_function(func=_decode_and_preprocess_eval, inp=[path, label], Tout=(tf.float32, tf.float32))
    img.set_shape([img_size[0], img_size[1], 3])
    lbl.set_shape([class_count])
    return img, lbl

# Rebuild tf.data datasets using the shape-aware wrappers
print('Rebuilding tf.data datasets with fixed shapes...')
train_paths = train_df['filepaths'].astype(str).values
train_labels = train_df['labels'].map(class_to_idx).values.astype('int32')
valid_paths = valid_df['filepaths'].astype(str).values
valid_labels = valid_df['labels'].map(class_to_idx).values.astype('int32')
test_paths = test_df['filepaths'].astype(str).values
test_labels = test_df['labels'].map(class_to_idx).values.astype('int32')

train_ds = tf.data.Dataset.from_tensor_slices((train_paths, train_labels))
train_ds = train_ds.shuffle(buffer_size=1000, seed=123)
train_ds = train_ds.map(_py_train, num_parallel_calls=AUTOTUNE)
train_ds = train_ds.batch(batch_size).prefetch(AUTOTUNE)

valid_ds = tf.data.Dataset.from_tensor_slices((valid_paths, valid_labels))
valid_ds = valid_ds.map(_py_eval, num_parallel_calls=AUTOTUNE)
valid_ds = valid_ds.batch(batch_size).prefetch(AUTOTUNE)

test_ds = tf.data.Dataset.from_tensor_slices((test_paths, test_labels))
test_ds = test_ds.map(_py_eval, num_parallel_calls=AUTOTUNE)
test_ds = test_ds.batch(batch_size).prefetch(AUTOTUNE)

# Recompute steps
train_steps = int(np.ceil(len(train_df) / batch_size))
valid_steps = int(np.ceil(len(valid_df) / batch_size))
test_steps = int(np.ceil(len(test_df) / batch_size))

print(f'  Train steps (batches): {train_steps}')
print(f'  Valid steps (batches): {valid_steps}')
print(f'  Test steps (batches): {test_steps}')
Out
Rebuilding tf.data datasets with fixed shapes...
  Train steps (batches): 24
  Valid steps (batches): 7
  Test steps (batches): 7
Check generator class distribution/center>
print('\n=== Dataset Class Distribution ===')
print('Train distribution:')
train_class_dist = train_df['labels'].value_counts().sort_index()
for class_name, count in train_class_dist.items():
    print(f'  {class_name:30s}: {count:4d} samples')

# Compute class weights (even with balanced data, slight weights help)
from sklearn.utils.class_weight import compute_class_weight

class_weights = compute_class_weight(
    class_weight='balanced',
    classes=np.arange(class_count),
    y=train_df['labels'].map(class_to_idx).values
)

class_weight_dict = dict(enumerate(class_weights))
print("\n=== Computed Class Weights ===")
for idx, class_name in enumerate(class_names):
    print(f"  {class_name:30s} -> Weight: {class_weight_dict[idx]:.4f}")

print("\n✓ Class weights will provide additional balancing during training")
Out
=== Dataset Class Distribution ===
Train distribution:
  Alternaria Leaf Spot          :  600 samples
  Bacterial Soft Rot            :  600 samples
  Black Rot                     :  600 samples
  Downy Mildew                  :  600 samples
  Healthy                       :  600 samples

=== Computed Class Weights ===
  Alternaria Leaf Spot           -> Weight: 1.0000
  Bacterial Soft Rot             -> Weight: 1.0000
  Black Rot                      -> Weight: 1.0000
  Downy Mildew                   -> Weight: 1.0000
  Healthy                        -> Weight: 1.0000

✓ Class weights will provide additional balancing during training
Create a function to show example training images
def show_image_samples_from_df(df, n=25):
    samp = df.sample(n=min(n, len(df)), random_state=123)
    plt.figure(figsize=(20, 20))
    for i, (_, row) in enumerate(samp.iterrows()):
        plt.subplot(5, 5, i + 1)
        img = Image.open(row['filepaths']).convert('RGB')
        img = img.resize((img_size[1], img_size[0]))
        plt.imshow(np.array(img) / 255.0)
        plt.title(row['labels'], color='blue', fontsize=14)
        plt.axis('off')
    plt.show()

show_image_samples_from_df(train_df)
Out
Output hidden; open in https://colab.research.google.com to view.
Create a model using transfer learning with EfficientNetB3
NOTE experts advise you make the base model initially not trainable. Then train for some number of epochs
then fine tune model by making base model trainable and run more epochs
I have found this to be WRONG!!!!
Making the base model trainable from the outset leads to faster convegence and a lower validation loss
for the same number of total epochs!
img_shape = (img_size[0], img_size[1], 3)
model_name = 'EfficientNetB3'

print(f'Building {model_name} model...')

# Create base model
base_model = tf.keras.applications.efficientnet.EfficientNetB3(
    include_top=False,
    weights="imagenet",
    input_shape=img_shape,
    pooling='max'
)

base_model.trainable = True

# Build model with MODERATE regularization
x = base_model.output
x = BatchNormalization(axis=-1, momentum=0.99, epsilon=0.001)(x)

# Add intermediate layer for better feature learning
x = Dense(512, activation='relu',
          kernel_regularizer=regularizers.l2(0.001))(x)
x = Dropout(rate=.45, seed=123)(x)

x = Dense(256, activation='relu',
          kernel_regularizer=regularizers.l2(0.001))(x)
x = Dropout(rate=.35, seed=123)(x)

# Output layer MUST be float32 for mixed precision
output = Dense(class_count, activation='softmax', dtype='float32', name='predictions')(x)

model = Model(inputs=base_model.input, outputs=output)

# Compile model with lower initial learning rate
lr = 0.0005  # Reduced from 0.001 for more stable training
model.compile(
    Adamax(learning_rate=lr),
    loss='categorical_crossentropy',
    metrics=['accuracy']
)

print(f'\n✓ Model compiled with learning rate: {lr}')
print(f'  Total parameters: {model.count_params():,}')
model.summary()
Out
Building EfficientNetB3 model...

✓ Model compiled with learning rate: 0.0005
  Total parameters: 11,709,236
Model: "functional"
┏━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━┓ ┃ Layer (type) ┃ Output Shape ┃ Param # ┃ Connected to ┃ ┡━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━┩ │ input_layer │ (None, 300, 300, │ 0 │ - │ │ (InputLayer) │ 3) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ rescaling │ (None, 300, 300, │ 0 │ input_layer[0][0] │ │ (Rescaling) │ 3) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ normalization │ (None, 300, 300, │ 7 │ rescaling[0][0] │ │ (Normalization) │ 3) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ rescaling_1 │ (None, 300, 300, │ 0 │ normalization[0]… │ │ (Rescaling) │ 3) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ stem_conv_pad │ (None, 301, 301, │ 0 │ rescaling_1[0][0] │ │ (ZeroPadding2D) │ 3) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ stem_conv (Conv2D) │ (None, 150, 150, │ 1,080 │ stem_conv_pad[0]… │ │ │ 40) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ stem_bn │ (None, 150, 150, │ 160 │ stem_conv[0][0] │ │ (BatchNormalizatio… │ 40) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ stem_activation │ (None, 150, 150, │ 0 │ stem_bn[0][0] │ │ (Activation) │ 40) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1a_dwconv │ (None, 150, 150, │ 360 │ stem_activation[… │ │ (DepthwiseConv2D) │ 40) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1a_bn │ (None, 150, 150, │ 160 │ block1a_dwconv[0… │ │ (BatchNormalizatio… │ 40) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1a_activation │ (None, 150, 150, │ 0 │ block1a_bn[0][0] │ │ (Activation) │ 40) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1a_se_squeeze │ (None, 40) │ 0 │ block1a_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1a_se_reshape │ (None, 1, 1, 40) │ 0 │ block1a_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1a_se_reduce │ (None, 1, 1, 10) │ 410 │ block1a_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1a_se_expand │ (None, 1, 1, 40) │ 440 │ block1a_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1a_se_excite │ (None, 150, 150, │ 0 │ block1a_activati… │ │ (Multiply) │ 40) │ │ block1a_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1a_project_co… │ (None, 150, 150, │ 960 │ block1a_se_excit… │ │ (Conv2D) │ 24) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1a_project_bn │ (None, 150, 150, │ 96 │ block1a_project_… │ │ (BatchNormalizatio… │ 24) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_dwconv │ (None, 150, 150, │ 216 │ block1a_project_… │ │ (DepthwiseConv2D) │ 24) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_bn │ (None, 150, 150, │ 96 │ block1b_dwconv[0… │ │ (BatchNormalizatio… │ 24) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_activation │ (None, 150, 150, │ 0 │ block1b_bn[0][0] │ │ (Activation) │ 24) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_se_squeeze │ (None, 24) │ 0 │ block1b_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_se_reshape │ (None, 1, 1, 24) │ 0 │ block1b_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_se_reduce │ (None, 1, 1, 6) │ 150 │ block1b_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_se_expand │ (None, 1, 1, 24) │ 168 │ block1b_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_se_excite │ (None, 150, 150, │ 0 │ block1b_activati… │ │ (Multiply) │ 24) │ │ block1b_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_project_co… │ (None, 150, 150, │ 576 │ block1b_se_excit… │ │ (Conv2D) │ 24) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_project_bn │ (None, 150, 150, │ 96 │ block1b_project_… │ │ (BatchNormalizatio… │ 24) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_drop │ (None, 150, 150, │ 0 │ block1b_project_… │ │ (Dropout) │ 24) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block1b_add (Add) │ (None, 150, 150, │ 0 │ block1b_drop[0][… │ │ │ 24) │ │ block1a_project_… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_expand_conv │ (None, 150, 150, │ 3,456 │ block1b_add[0][0] │ │ (Conv2D) │ 144) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_expand_bn │ (None, 150, 150, │ 576 │ block2a_expand_c… │ │ (BatchNormalizatio… │ 144) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_expand_act… │ (None, 150, 150, │ 0 │ block2a_expand_b… │ │ (Activation) │ 144) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_dwconv_pad │ (None, 151, 151, │ 0 │ block2a_expand_a… │ │ (ZeroPadding2D) │ 144) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_dwconv │ (None, 75, 75, │ 1,296 │ block2a_dwconv_p… │ │ (DepthwiseConv2D) │ 144) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_bn │ (None, 75, 75, │ 576 │ block2a_dwconv[0… │ │ (BatchNormalizatio… │ 144) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_activation │ (None, 75, 75, │ 0 │ block2a_bn[0][0] │ │ (Activation) │ 144) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_se_squeeze │ (None, 144) │ 0 │ block2a_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_se_reshape │ (None, 1, 1, 144) │ 0 │ block2a_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_se_reduce │ (None, 1, 1, 6) │ 870 │ block2a_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_se_expand │ (None, 1, 1, 144) │ 1,008 │ block2a_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_se_excite │ (None, 75, 75, │ 0 │ block2a_activati… │ │ (Multiply) │ 144) │ │ block2a_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_project_co… │ (None, 75, 75, │ 4,608 │ block2a_se_excit… │ │ (Conv2D) │ 32) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2a_project_bn │ (None, 75, 75, │ 128 │ block2a_project_… │ │ (BatchNormalizatio… │ 32) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_expand_conv │ (None, 75, 75, │ 6,144 │ block2a_project_… │ │ (Conv2D) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_expand_bn │ (None, 75, 75, │ 768 │ block2b_expand_c… │ │ (BatchNormalizatio… │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_expand_act… │ (None, 75, 75, │ 0 │ block2b_expand_b… │ │ (Activation) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_dwconv │ (None, 75, 75, │ 1,728 │ block2b_expand_a… │ │ (DepthwiseConv2D) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_bn │ (None, 75, 75, │ 768 │ block2b_dwconv[0… │ │ (BatchNormalizatio… │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_activation │ (None, 75, 75, │ 0 │ block2b_bn[0][0] │ │ (Activation) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_se_squeeze │ (None, 192) │ 0 │ block2b_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_se_reshape │ (None, 1, 1, 192) │ 0 │ block2b_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_se_reduce │ (None, 1, 1, 8) │ 1,544 │ block2b_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_se_expand │ (None, 1, 1, 192) │ 1,728 │ block2b_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_se_excite │ (None, 75, 75, │ 0 │ block2b_activati… │ │ (Multiply) │ 192) │ │ block2b_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_project_co… │ (None, 75, 75, │ 6,144 │ block2b_se_excit… │ │ (Conv2D) │ 32) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_project_bn │ (None, 75, 75, │ 128 │ block2b_project_… │ │ (BatchNormalizatio… │ 32) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_drop │ (None, 75, 75, │ 0 │ block2b_project_… │ │ (Dropout) │ 32) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2b_add (Add) │ (None, 75, 75, │ 0 │ block2b_drop[0][… │ │ │ 32) │ │ block2a_project_… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_expand_conv │ (None, 75, 75, │ 6,144 │ block2b_add[0][0] │ │ (Conv2D) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_expand_bn │ (None, 75, 75, │ 768 │ block2c_expand_c… │ │ (BatchNormalizatio… │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_expand_act… │ (None, 75, 75, │ 0 │ block2c_expand_b… │ │ (Activation) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_dwconv │ (None, 75, 75, │ 1,728 │ block2c_expand_a… │ │ (DepthwiseConv2D) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_bn │ (None, 75, 75, │ 768 │ block2c_dwconv[0… │ │ (BatchNormalizatio… │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_activation │ (None, 75, 75, │ 0 │ block2c_bn[0][0] │ │ (Activation) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_se_squeeze │ (None, 192) │ 0 │ block2c_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_se_reshape │ (None, 1, 1, 192) │ 0 │ block2c_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_se_reduce │ (None, 1, 1, 8) │ 1,544 │ block2c_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_se_expand │ (None, 1, 1, 192) │ 1,728 │ block2c_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_se_excite │ (None, 75, 75, │ 0 │ block2c_activati… │ │ (Multiply) │ 192) │ │ block2c_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_project_co… │ (None, 75, 75, │ 6,144 │ block2c_se_excit… │ │ (Conv2D) │ 32) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_project_bn │ (None, 75, 75, │ 128 │ block2c_project_… │ │ (BatchNormalizatio… │ 32) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_drop │ (None, 75, 75, │ 0 │ block2c_project_… │ │ (Dropout) │ 32) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block2c_add (Add) │ (None, 75, 75, │ 0 │ block2c_drop[0][… │ │ │ 32) │ │ block2b_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_expand_conv │ (None, 75, 75, │ 6,144 │ block2c_add[0][0] │ │ (Conv2D) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_expand_bn │ (None, 75, 75, │ 768 │ block3a_expand_c… │ │ (BatchNormalizatio… │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_expand_act… │ (None, 75, 75, │ 0 │ block3a_expand_b… │ │ (Activation) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_dwconv_pad │ (None, 79, 79, │ 0 │ block3a_expand_a… │ │ (ZeroPadding2D) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_dwconv │ (None, 38, 38, │ 4,800 │ block3a_dwconv_p… │ │ (DepthwiseConv2D) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_bn │ (None, 38, 38, │ 768 │ block3a_dwconv[0… │ │ (BatchNormalizatio… │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_activation │ (None, 38, 38, │ 0 │ block3a_bn[0][0] │ │ (Activation) │ 192) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_se_squeeze │ (None, 192) │ 0 │ block3a_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_se_reshape │ (None, 1, 1, 192) │ 0 │ block3a_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_se_reduce │ (None, 1, 1, 8) │ 1,544 │ block3a_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_se_expand │ (None, 1, 1, 192) │ 1,728 │ block3a_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_se_excite │ (None, 38, 38, │ 0 │ block3a_activati… │ │ (Multiply) │ 192) │ │ block3a_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_project_co… │ (None, 38, 38, │ 9,216 │ block3a_se_excit… │ │ (Conv2D) │ 48) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3a_project_bn │ (None, 38, 38, │ 192 │ block3a_project_… │ │ (BatchNormalizatio… │ 48) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_expand_conv │ (None, 38, 38, │ 13,824 │ block3a_project_… │ │ (Conv2D) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_expand_bn │ (None, 38, 38, │ 1,152 │ block3b_expand_c… │ │ (BatchNormalizatio… │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_expand_act… │ (None, 38, 38, │ 0 │ block3b_expand_b… │ │ (Activation) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_dwconv │ (None, 38, 38, │ 7,200 │ block3b_expand_a… │ │ (DepthwiseConv2D) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_bn │ (None, 38, 38, │ 1,152 │ block3b_dwconv[0… │ │ (BatchNormalizatio… │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_activation │ (None, 38, 38, │ 0 │ block3b_bn[0][0] │ │ (Activation) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_se_squeeze │ (None, 288) │ 0 │ block3b_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_se_reshape │ (None, 1, 1, 288) │ 0 │ block3b_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_se_reduce │ (None, 1, 1, 12) │ 3,468 │ block3b_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_se_expand │ (None, 1, 1, 288) │ 3,744 │ block3b_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_se_excite │ (None, 38, 38, │ 0 │ block3b_activati… │ │ (Multiply) │ 288) │ │ block3b_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_project_co… │ (None, 38, 38, │ 13,824 │ block3b_se_excit… │ │ (Conv2D) │ 48) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_project_bn │ (None, 38, 38, │ 192 │ block3b_project_… │ │ (BatchNormalizatio… │ 48) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_drop │ (None, 38, 38, │ 0 │ block3b_project_… │ │ (Dropout) │ 48) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3b_add (Add) │ (None, 38, 38, │ 0 │ block3b_drop[0][… │ │ │ 48) │ │ block3a_project_… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_expand_conv │ (None, 38, 38, │ 13,824 │ block3b_add[0][0] │ │ (Conv2D) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_expand_bn │ (None, 38, 38, │ 1,152 │ block3c_expand_c… │ │ (BatchNormalizatio… │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_expand_act… │ (None, 38, 38, │ 0 │ block3c_expand_b… │ │ (Activation) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_dwconv │ (None, 38, 38, │ 7,200 │ block3c_expand_a… │ │ (DepthwiseConv2D) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_bn │ (None, 38, 38, │ 1,152 │ block3c_dwconv[0… │ │ (BatchNormalizatio… │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_activation │ (None, 38, 38, │ 0 │ block3c_bn[0][0] │ │ (Activation) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_se_squeeze │ (None, 288) │ 0 │ block3c_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_se_reshape │ (None, 1, 1, 288) │ 0 │ block3c_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_se_reduce │ (None, 1, 1, 12) │ 3,468 │ block3c_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_se_expand │ (None, 1, 1, 288) │ 3,744 │ block3c_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_se_excite │ (None, 38, 38, │ 0 │ block3c_activati… │ │ (Multiply) │ 288) │ │ block3c_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_project_co… │ (None, 38, 38, │ 13,824 │ block3c_se_excit… │ │ (Conv2D) │ 48) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_project_bn │ (None, 38, 38, │ 192 │ block3c_project_… │ │ (BatchNormalizatio… │ 48) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_drop │ (None, 38, 38, │ 0 │ block3c_project_… │ │ (Dropout) │ 48) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block3c_add (Add) │ (None, 38, 38, │ 0 │ block3c_drop[0][… │ │ │ 48) │ │ block3b_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_expand_conv │ (None, 38, 38, │ 13,824 │ block3c_add[0][0] │ │ (Conv2D) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_expand_bn │ (None, 38, 38, │ 1,152 │ block4a_expand_c… │ │ (BatchNormalizatio… │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_expand_act… │ (None, 38, 38, │ 0 │ block4a_expand_b… │ │ (Activation) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_dwconv_pad │ (None, 39, 39, │ 0 │ block4a_expand_a… │ │ (ZeroPadding2D) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_dwconv │ (None, 19, 19, │ 2,592 │ block4a_dwconv_p… │ │ (DepthwiseConv2D) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_bn │ (None, 19, 19, │ 1,152 │ block4a_dwconv[0… │ │ (BatchNormalizatio… │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_activation │ (None, 19, 19, │ 0 │ block4a_bn[0][0] │ │ (Activation) │ 288) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_se_squeeze │ (None, 288) │ 0 │ block4a_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_se_reshape │ (None, 1, 1, 288) │ 0 │ block4a_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_se_reduce │ (None, 1, 1, 12) │ 3,468 │ block4a_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_se_expand │ (None, 1, 1, 288) │ 3,744 │ block4a_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_se_excite │ (None, 19, 19, │ 0 │ block4a_activati… │ │ (Multiply) │ 288) │ │ block4a_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_project_co… │ (None, 19, 19, │ 27,648 │ block4a_se_excit… │ │ (Conv2D) │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4a_project_bn │ (None, 19, 19, │ 384 │ block4a_project_… │ │ (BatchNormalizatio… │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_expand_conv │ (None, 19, 19, │ 55,296 │ block4a_project_… │ │ (Conv2D) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_expand_bn │ (None, 19, 19, │ 2,304 │ block4b_expand_c… │ │ (BatchNormalizatio… │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_expand_act… │ (None, 19, 19, │ 0 │ block4b_expand_b… │ │ (Activation) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_dwconv │ (None, 19, 19, │ 5,184 │ block4b_expand_a… │ │ (DepthwiseConv2D) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_bn │ (None, 19, 19, │ 2,304 │ block4b_dwconv[0… │ │ (BatchNormalizatio… │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_activation │ (None, 19, 19, │ 0 │ block4b_bn[0][0] │ │ (Activation) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_se_squeeze │ (None, 576) │ 0 │ block4b_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_se_reshape │ (None, 1, 1, 576) │ 0 │ block4b_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_se_reduce │ (None, 1, 1, 24) │ 13,848 │ block4b_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_se_expand │ (None, 1, 1, 576) │ 14,400 │ block4b_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_se_excite │ (None, 19, 19, │ 0 │ block4b_activati… │ │ (Multiply) │ 576) │ │ block4b_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_project_co… │ (None, 19, 19, │ 55,296 │ block4b_se_excit… │ │ (Conv2D) │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_project_bn │ (None, 19, 19, │ 384 │ block4b_project_… │ │ (BatchNormalizatio… │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_drop │ (None, 19, 19, │ 0 │ block4b_project_… │ │ (Dropout) │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4b_add (Add) │ (None, 19, 19, │ 0 │ block4b_drop[0][… │ │ │ 96) │ │ block4a_project_… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_expand_conv │ (None, 19, 19, │ 55,296 │ block4b_add[0][0] │ │ (Conv2D) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_expand_bn │ (None, 19, 19, │ 2,304 │ block4c_expand_c… │ │ (BatchNormalizatio… │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_expand_act… │ (None, 19, 19, │ 0 │ block4c_expand_b… │ │ (Activation) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_dwconv │ (None, 19, 19, │ 5,184 │ block4c_expand_a… │ │ (DepthwiseConv2D) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_bn │ (None, 19, 19, │ 2,304 │ block4c_dwconv[0… │ │ (BatchNormalizatio… │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_activation │ (None, 19, 19, │ 0 │ block4c_bn[0][0] │ │ (Activation) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_se_squeeze │ (None, 576) │ 0 │ block4c_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_se_reshape │ (None, 1, 1, 576) │ 0 │ block4c_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_se_reduce │ (None, 1, 1, 24) │ 13,848 │ block4c_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_se_expand │ (None, 1, 1, 576) │ 14,400 │ block4c_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_se_excite │ (None, 19, 19, │ 0 │ block4c_activati… │ │ (Multiply) │ 576) │ │ block4c_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_project_co… │ (None, 19, 19, │ 55,296 │ block4c_se_excit… │ │ (Conv2D) │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_project_bn │ (None, 19, 19, │ 384 │ block4c_project_… │ │ (BatchNormalizatio… │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_drop │ (None, 19, 19, │ 0 │ block4c_project_… │ │ (Dropout) │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4c_add (Add) │ (None, 19, 19, │ 0 │ block4c_drop[0][… │ │ │ 96) │ │ block4b_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_expand_conv │ (None, 19, 19, │ 55,296 │ block4c_add[0][0] │ │ (Conv2D) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_expand_bn │ (None, 19, 19, │ 2,304 │ block4d_expand_c… │ │ (BatchNormalizatio… │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_expand_act… │ (None, 19, 19, │ 0 │ block4d_expand_b… │ │ (Activation) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_dwconv │ (None, 19, 19, │ 5,184 │ block4d_expand_a… │ │ (DepthwiseConv2D) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_bn │ (None, 19, 19, │ 2,304 │ block4d_dwconv[0… │ │ (BatchNormalizatio… │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_activation │ (None, 19, 19, │ 0 │ block4d_bn[0][0] │ │ (Activation) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_se_squeeze │ (None, 576) │ 0 │ block4d_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_se_reshape │ (None, 1, 1, 576) │ 0 │ block4d_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_se_reduce │ (None, 1, 1, 24) │ 13,848 │ block4d_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_se_expand │ (None, 1, 1, 576) │ 14,400 │ block4d_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_se_excite │ (None, 19, 19, │ 0 │ block4d_activati… │ │ (Multiply) │ 576) │ │ block4d_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_project_co… │ (None, 19, 19, │ 55,296 │ block4d_se_excit… │ │ (Conv2D) │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_project_bn │ (None, 19, 19, │ 384 │ block4d_project_… │ │ (BatchNormalizatio… │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_drop │ (None, 19, 19, │ 0 │ block4d_project_… │ │ (Dropout) │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4d_add (Add) │ (None, 19, 19, │ 0 │ block4d_drop[0][… │ │ │ 96) │ │ block4c_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_expand_conv │ (None, 19, 19, │ 55,296 │ block4d_add[0][0] │ │ (Conv2D) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_expand_bn │ (None, 19, 19, │ 2,304 │ block4e_expand_c… │ │ (BatchNormalizatio… │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_expand_act… │ (None, 19, 19, │ 0 │ block4e_expand_b… │ │ (Activation) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_dwconv │ (None, 19, 19, │ 5,184 │ block4e_expand_a… │ │ (DepthwiseConv2D) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_bn │ (None, 19, 19, │ 2,304 │ block4e_dwconv[0… │ │ (BatchNormalizatio… │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_activation │ (None, 19, 19, │ 0 │ block4e_bn[0][0] │ │ (Activation) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_se_squeeze │ (None, 576) │ 0 │ block4e_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_se_reshape │ (None, 1, 1, 576) │ 0 │ block4e_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_se_reduce │ (None, 1, 1, 24) │ 13,848 │ block4e_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_se_expand │ (None, 1, 1, 576) │ 14,400 │ block4e_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_se_excite │ (None, 19, 19, │ 0 │ block4e_activati… │ │ (Multiply) │ 576) │ │ block4e_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_project_co… │ (None, 19, 19, │ 55,296 │ block4e_se_excit… │ │ (Conv2D) │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_project_bn │ (None, 19, 19, │ 384 │ block4e_project_… │ │ (BatchNormalizatio… │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_drop │ (None, 19, 19, │ 0 │ block4e_project_… │ │ (Dropout) │ 96) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block4e_add (Add) │ (None, 19, 19, │ 0 │ block4e_drop[0][… │ │ │ 96) │ │ block4d_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_expand_conv │ (None, 19, 19, │ 55,296 │ block4e_add[0][0] │ │ (Conv2D) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_expand_bn │ (None, 19, 19, │ 2,304 │ block5a_expand_c… │ │ (BatchNormalizatio… │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_expand_act… │ (None, 19, 19, │ 0 │ block5a_expand_b… │ │ (Activation) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_dwconv │ (None, 19, 19, │ 14,400 │ block5a_expand_a… │ │ (DepthwiseConv2D) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_bn │ (None, 19, 19, │ 2,304 │ block5a_dwconv[0… │ │ (BatchNormalizatio… │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_activation │ (None, 19, 19, │ 0 │ block5a_bn[0][0] │ │ (Activation) │ 576) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_se_squeeze │ (None, 576) │ 0 │ block5a_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_se_reshape │ (None, 1, 1, 576) │ 0 │ block5a_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_se_reduce │ (None, 1, 1, 24) │ 13,848 │ block5a_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_se_expand │ (None, 1, 1, 576) │ 14,400 │ block5a_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_se_excite │ (None, 19, 19, │ 0 │ block5a_activati… │ │ (Multiply) │ 576) │ │ block5a_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_project_co… │ (None, 19, 19, │ 78,336 │ block5a_se_excit… │ │ (Conv2D) │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5a_project_bn │ (None, 19, 19, │ 544 │ block5a_project_… │ │ (BatchNormalizatio… │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_expand_conv │ (None, 19, 19, │ 110,976 │ block5a_project_… │ │ (Conv2D) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_expand_bn │ (None, 19, 19, │ 3,264 │ block5b_expand_c… │ │ (BatchNormalizatio… │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_expand_act… │ (None, 19, 19, │ 0 │ block5b_expand_b… │ │ (Activation) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_dwconv │ (None, 19, 19, │ 20,400 │ block5b_expand_a… │ │ (DepthwiseConv2D) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_bn │ (None, 19, 19, │ 3,264 │ block5b_dwconv[0… │ │ (BatchNormalizatio… │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_activation │ (None, 19, 19, │ 0 │ block5b_bn[0][0] │ │ (Activation) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_se_squeeze │ (None, 816) │ 0 │ block5b_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_se_reshape │ (None, 1, 1, 816) │ 0 │ block5b_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_se_reduce │ (None, 1, 1, 34) │ 27,778 │ block5b_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_se_expand │ (None, 1, 1, 816) │ 28,560 │ block5b_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_se_excite │ (None, 19, 19, │ 0 │ block5b_activati… │ │ (Multiply) │ 816) │ │ block5b_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_project_co… │ (None, 19, 19, │ 110,976 │ block5b_se_excit… │ │ (Conv2D) │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_project_bn │ (None, 19, 19, │ 544 │ block5b_project_… │ │ (BatchNormalizatio… │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_drop │ (None, 19, 19, │ 0 │ block5b_project_… │ │ (Dropout) │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5b_add (Add) │ (None, 19, 19, │ 0 │ block5b_drop[0][… │ │ │ 136) │ │ block5a_project_… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_expand_conv │ (None, 19, 19, │ 110,976 │ block5b_add[0][0] │ │ (Conv2D) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_expand_bn │ (None, 19, 19, │ 3,264 │ block5c_expand_c… │ │ (BatchNormalizatio… │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_expand_act… │ (None, 19, 19, │ 0 │ block5c_expand_b… │ │ (Activation) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_dwconv │ (None, 19, 19, │ 20,400 │ block5c_expand_a… │ │ (DepthwiseConv2D) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_bn │ (None, 19, 19, │ 3,264 │ block5c_dwconv[0… │ │ (BatchNormalizatio… │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_activation │ (None, 19, 19, │ 0 │ block5c_bn[0][0] │ │ (Activation) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_se_squeeze │ (None, 816) │ 0 │ block5c_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_se_reshape │ (None, 1, 1, 816) │ 0 │ block5c_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_se_reduce │ (None, 1, 1, 34) │ 27,778 │ block5c_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_se_expand │ (None, 1, 1, 816) │ 28,560 │ block5c_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_se_excite │ (None, 19, 19, │ 0 │ block5c_activati… │ │ (Multiply) │ 816) │ │ block5c_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_project_co… │ (None, 19, 19, │ 110,976 │ block5c_se_excit… │ │ (Conv2D) │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_project_bn │ (None, 19, 19, │ 544 │ block5c_project_… │ │ (BatchNormalizatio… │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_drop │ (None, 19, 19, │ 0 │ block5c_project_… │ │ (Dropout) │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5c_add (Add) │ (None, 19, 19, │ 0 │ block5c_drop[0][… │ │ │ 136) │ │ block5b_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_expand_conv │ (None, 19, 19, │ 110,976 │ block5c_add[0][0] │ │ (Conv2D) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_expand_bn │ (None, 19, 19, │ 3,264 │ block5d_expand_c… │ │ (BatchNormalizatio… │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_expand_act… │ (None, 19, 19, │ 0 │ block5d_expand_b… │ │ (Activation) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_dwconv │ (None, 19, 19, │ 20,400 │ block5d_expand_a… │ │ (DepthwiseConv2D) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_bn │ (None, 19, 19, │ 3,264 │ block5d_dwconv[0… │ │ (BatchNormalizatio… │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_activation │ (None, 19, 19, │ 0 │ block5d_bn[0][0] │ │ (Activation) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_se_squeeze │ (None, 816) │ 0 │ block5d_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_se_reshape │ (None, 1, 1, 816) │ 0 │ block5d_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_se_reduce │ (None, 1, 1, 34) │ 27,778 │ block5d_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_se_expand │ (None, 1, 1, 816) │ 28,560 │ block5d_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_se_excite │ (None, 19, 19, │ 0 │ block5d_activati… │ │ (Multiply) │ 816) │ │ block5d_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_project_co… │ (None, 19, 19, │ 110,976 │ block5d_se_excit… │ │ (Conv2D) │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_project_bn │ (None, 19, 19, │ 544 │ block5d_project_… │ │ (BatchNormalizatio… │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_drop │ (None, 19, 19, │ 0 │ block5d_project_… │ │ (Dropout) │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5d_add (Add) │ (None, 19, 19, │ 0 │ block5d_drop[0][… │ │ │ 136) │ │ block5c_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_expand_conv │ (None, 19, 19, │ 110,976 │ block5d_add[0][0] │ │ (Conv2D) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_expand_bn │ (None, 19, 19, │ 3,264 │ block5e_expand_c… │ │ (BatchNormalizatio… │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_expand_act… │ (None, 19, 19, │ 0 │ block5e_expand_b… │ │ (Activation) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_dwconv │ (None, 19, 19, │ 20,400 │ block5e_expand_a… │ │ (DepthwiseConv2D) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_bn │ (None, 19, 19, │ 3,264 │ block5e_dwconv[0… │ │ (BatchNormalizatio… │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_activation │ (None, 19, 19, │ 0 │ block5e_bn[0][0] │ │ (Activation) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_se_squeeze │ (None, 816) │ 0 │ block5e_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_se_reshape │ (None, 1, 1, 816) │ 0 │ block5e_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_se_reduce │ (None, 1, 1, 34) │ 27,778 │ block5e_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_se_expand │ (None, 1, 1, 816) │ 28,560 │ block5e_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_se_excite │ (None, 19, 19, │ 0 │ block5e_activati… │ │ (Multiply) │ 816) │ │ block5e_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_project_co… │ (None, 19, 19, │ 110,976 │ block5e_se_excit… │ │ (Conv2D) │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_project_bn │ (None, 19, 19, │ 544 │ block5e_project_… │ │ (BatchNormalizatio… │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_drop │ (None, 19, 19, │ 0 │ block5e_project_… │ │ (Dropout) │ 136) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block5e_add (Add) │ (None, 19, 19, │ 0 │ block5e_drop[0][… │ │ │ 136) │ │ block5d_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_expand_conv │ (None, 19, 19, │ 110,976 │ block5e_add[0][0] │ │ (Conv2D) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_expand_bn │ (None, 19, 19, │ 3,264 │ block6a_expand_c… │ │ (BatchNormalizatio… │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_expand_act… │ (None, 19, 19, │ 0 │ block6a_expand_b… │ │ (Activation) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_dwconv_pad │ (None, 23, 23, │ 0 │ block6a_expand_a… │ │ (ZeroPadding2D) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_dwconv │ (None, 10, 10, │ 20,400 │ block6a_dwconv_p… │ │ (DepthwiseConv2D) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_bn │ (None, 10, 10, │ 3,264 │ block6a_dwconv[0… │ │ (BatchNormalizatio… │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_activation │ (None, 10, 10, │ 0 │ block6a_bn[0][0] │ │ (Activation) │ 816) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_se_squeeze │ (None, 816) │ 0 │ block6a_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_se_reshape │ (None, 1, 1, 816) │ 0 │ block6a_se_squee… │ │ (Reshape) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_se_reduce │ (None, 1, 1, 34) │ 27,778 │ block6a_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_se_expand │ (None, 1, 1, 816) │ 28,560 │ block6a_se_reduc… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_se_excite │ (None, 10, 10, │ 0 │ block6a_activati… │ │ (Multiply) │ 816) │ │ block6a_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_project_co… │ (None, 10, 10, │ 189,312 │ block6a_se_excit… │ │ (Conv2D) │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6a_project_bn │ (None, 10, 10, │ 928 │ block6a_project_… │ │ (BatchNormalizatio… │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_expand_conv │ (None, 10, 10, │ 322,944 │ block6a_project_… │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_expand_bn │ (None, 10, 10, │ 5,568 │ block6b_expand_c… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_expand_act… │ (None, 10, 10, │ 0 │ block6b_expand_b… │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_dwconv │ (None, 10, 10, │ 34,800 │ block6b_expand_a… │ │ (DepthwiseConv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_bn │ (None, 10, 10, │ 5,568 │ block6b_dwconv[0… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_activation │ (None, 10, 10, │ 0 │ block6b_bn[0][0] │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_se_squeeze │ (None, 1392) │ 0 │ block6b_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_se_reshape │ (None, 1, 1, │ 0 │ block6b_se_squee… │ │ (Reshape) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_se_reduce │ (None, 1, 1, 58) │ 80,794 │ block6b_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_se_expand │ (None, 1, 1, │ 82,128 │ block6b_se_reduc… │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_se_excite │ (None, 10, 10, │ 0 │ block6b_activati… │ │ (Multiply) │ 1392) │ │ block6b_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_project_co… │ (None, 10, 10, │ 322,944 │ block6b_se_excit… │ │ (Conv2D) │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_project_bn │ (None, 10, 10, │ 928 │ block6b_project_… │ │ (BatchNormalizatio… │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_drop │ (None, 10, 10, │ 0 │ block6b_project_… │ │ (Dropout) │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6b_add (Add) │ (None, 10, 10, │ 0 │ block6b_drop[0][… │ │ │ 232) │ │ block6a_project_… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_expand_conv │ (None, 10, 10, │ 322,944 │ block6b_add[0][0] │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_expand_bn │ (None, 10, 10, │ 5,568 │ block6c_expand_c… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_expand_act… │ (None, 10, 10, │ 0 │ block6c_expand_b… │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_dwconv │ (None, 10, 10, │ 34,800 │ block6c_expand_a… │ │ (DepthwiseConv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_bn │ (None, 10, 10, │ 5,568 │ block6c_dwconv[0… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_activation │ (None, 10, 10, │ 0 │ block6c_bn[0][0] │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_se_squeeze │ (None, 1392) │ 0 │ block6c_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_se_reshape │ (None, 1, 1, │ 0 │ block6c_se_squee… │ │ (Reshape) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_se_reduce │ (None, 1, 1, 58) │ 80,794 │ block6c_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_se_expand │ (None, 1, 1, │ 82,128 │ block6c_se_reduc… │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_se_excite │ (None, 10, 10, │ 0 │ block6c_activati… │ │ (Multiply) │ 1392) │ │ block6c_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_project_co… │ (None, 10, 10, │ 322,944 │ block6c_se_excit… │ │ (Conv2D) │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_project_bn │ (None, 10, 10, │ 928 │ block6c_project_… │ │ (BatchNormalizatio… │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_drop │ (None, 10, 10, │ 0 │ block6c_project_… │ │ (Dropout) │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6c_add (Add) │ (None, 10, 10, │ 0 │ block6c_drop[0][… │ │ │ 232) │ │ block6b_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_expand_conv │ (None, 10, 10, │ 322,944 │ block6c_add[0][0] │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_expand_bn │ (None, 10, 10, │ 5,568 │ block6d_expand_c… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_expand_act… │ (None, 10, 10, │ 0 │ block6d_expand_b… │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_dwconv │ (None, 10, 10, │ 34,800 │ block6d_expand_a… │ │ (DepthwiseConv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_bn │ (None, 10, 10, │ 5,568 │ block6d_dwconv[0… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_activation │ (None, 10, 10, │ 0 │ block6d_bn[0][0] │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_se_squeeze │ (None, 1392) │ 0 │ block6d_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_se_reshape │ (None, 1, 1, │ 0 │ block6d_se_squee… │ │ (Reshape) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_se_reduce │ (None, 1, 1, 58) │ 80,794 │ block6d_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_se_expand │ (None, 1, 1, │ 82,128 │ block6d_se_reduc… │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_se_excite │ (None, 10, 10, │ 0 │ block6d_activati… │ │ (Multiply) │ 1392) │ │ block6d_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_project_co… │ (None, 10, 10, │ 322,944 │ block6d_se_excit… │ │ (Conv2D) │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_project_bn │ (None, 10, 10, │ 928 │ block6d_project_… │ │ (BatchNormalizatio… │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_drop │ (None, 10, 10, │ 0 │ block6d_project_… │ │ (Dropout) │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6d_add (Add) │ (None, 10, 10, │ 0 │ block6d_drop[0][… │ │ │ 232) │ │ block6c_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_expand_conv │ (None, 10, 10, │ 322,944 │ block6d_add[0][0] │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_expand_bn │ (None, 10, 10, │ 5,568 │ block6e_expand_c… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_expand_act… │ (None, 10, 10, │ 0 │ block6e_expand_b… │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_dwconv │ (None, 10, 10, │ 34,800 │ block6e_expand_a… │ │ (DepthwiseConv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_bn │ (None, 10, 10, │ 5,568 │ block6e_dwconv[0… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_activation │ (None, 10, 10, │ 0 │ block6e_bn[0][0] │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_se_squeeze │ (None, 1392) │ 0 │ block6e_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_se_reshape │ (None, 1, 1, │ 0 │ block6e_se_squee… │ │ (Reshape) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_se_reduce │ (None, 1, 1, 58) │ 80,794 │ block6e_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_se_expand │ (None, 1, 1, │ 82,128 │ block6e_se_reduc… │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_se_excite │ (None, 10, 10, │ 0 │ block6e_activati… │ │ (Multiply) │ 1392) │ │ block6e_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_project_co… │ (None, 10, 10, │ 322,944 │ block6e_se_excit… │ │ (Conv2D) │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_project_bn │ (None, 10, 10, │ 928 │ block6e_project_… │ │ (BatchNormalizatio… │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_drop │ (None, 10, 10, │ 0 │ block6e_project_… │ │ (Dropout) │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6e_add (Add) │ (None, 10, 10, │ 0 │ block6e_drop[0][… │ │ │ 232) │ │ block6d_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_expand_conv │ (None, 10, 10, │ 322,944 │ block6e_add[0][0] │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_expand_bn │ (None, 10, 10, │ 5,568 │ block6f_expand_c… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_expand_act… │ (None, 10, 10, │ 0 │ block6f_expand_b… │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_dwconv │ (None, 10, 10, │ 34,800 │ block6f_expand_a… │ │ (DepthwiseConv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_bn │ (None, 10, 10, │ 5,568 │ block6f_dwconv[0… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_activation │ (None, 10, 10, │ 0 │ block6f_bn[0][0] │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_se_squeeze │ (None, 1392) │ 0 │ block6f_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_se_reshape │ (None, 1, 1, │ 0 │ block6f_se_squee… │ │ (Reshape) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_se_reduce │ (None, 1, 1, 58) │ 80,794 │ block6f_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_se_expand │ (None, 1, 1, │ 82,128 │ block6f_se_reduc… │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_se_excite │ (None, 10, 10, │ 0 │ block6f_activati… │ │ (Multiply) │ 1392) │ │ block6f_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_project_co… │ (None, 10, 10, │ 322,944 │ block6f_se_excit… │ │ (Conv2D) │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_project_bn │ (None, 10, 10, │ 928 │ block6f_project_… │ │ (BatchNormalizatio… │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_drop │ (None, 10, 10, │ 0 │ block6f_project_… │ │ (Dropout) │ 232) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block6f_add (Add) │ (None, 10, 10, │ 0 │ block6f_drop[0][… │ │ │ 232) │ │ block6e_add[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_expand_conv │ (None, 10, 10, │ 322,944 │ block6f_add[0][0] │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_expand_bn │ (None, 10, 10, │ 5,568 │ block7a_expand_c… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_expand_act… │ (None, 10, 10, │ 0 │ block7a_expand_b… │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_dwconv │ (None, 10, 10, │ 12,528 │ block7a_expand_a… │ │ (DepthwiseConv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_bn │ (None, 10, 10, │ 5,568 │ block7a_dwconv[0… │ │ (BatchNormalizatio… │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_activation │ (None, 10, 10, │ 0 │ block7a_bn[0][0] │ │ (Activation) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_se_squeeze │ (None, 1392) │ 0 │ block7a_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_se_reshape │ (None, 1, 1, │ 0 │ block7a_se_squee… │ │ (Reshape) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_se_reduce │ (None, 1, 1, 58) │ 80,794 │ block7a_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_se_expand │ (None, 1, 1, │ 82,128 │ block7a_se_reduc… │ │ (Conv2D) │ 1392) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_se_excite │ (None, 10, 10, │ 0 │ block7a_activati… │ │ (Multiply) │ 1392) │ │ block7a_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_project_co… │ (None, 10, 10, │ 534,528 │ block7a_se_excit… │ │ (Conv2D) │ 384) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7a_project_bn │ (None, 10, 10, │ 1,536 │ block7a_project_… │ │ (BatchNormalizatio… │ 384) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_expand_conv │ (None, 10, 10, │ 884,736 │ block7a_project_… │ │ (Conv2D) │ 2304) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_expand_bn │ (None, 10, 10, │ 9,216 │ block7b_expand_c… │ │ (BatchNormalizatio… │ 2304) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_expand_act… │ (None, 10, 10, │ 0 │ block7b_expand_b… │ │ (Activation) │ 2304) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_dwconv │ (None, 10, 10, │ 20,736 │ block7b_expand_a… │ │ (DepthwiseConv2D) │ 2304) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_bn │ (None, 10, 10, │ 9,216 │ block7b_dwconv[0… │ │ (BatchNormalizatio… │ 2304) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_activation │ (None, 10, 10, │ 0 │ block7b_bn[0][0] │ │ (Activation) │ 2304) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_se_squeeze │ (None, 2304) │ 0 │ block7b_activati… │ │ (GlobalAveragePool… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_se_reshape │ (None, 1, 1, │ 0 │ block7b_se_squee… │ │ (Reshape) │ 2304) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_se_reduce │ (None, 1, 1, 96) │ 221,280 │ block7b_se_resha… │ │ (Conv2D) │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_se_expand │ (None, 1, 1, │ 223,488 │ block7b_se_reduc… │ │ (Conv2D) │ 2304) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_se_excite │ (None, 10, 10, │ 0 │ block7b_activati… │ │ (Multiply) │ 2304) │ │ block7b_se_expan… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_project_co… │ (None, 10, 10, │ 884,736 │ block7b_se_excit… │ │ (Conv2D) │ 384) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_project_bn │ (None, 10, 10, │ 1,536 │ block7b_project_… │ │ (BatchNormalizatio… │ 384) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_drop │ (None, 10, 10, │ 0 │ block7b_project_… │ │ (Dropout) │ 384) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ block7b_add (Add) │ (None, 10, 10, │ 0 │ block7b_drop[0][… │ │ │ 384) │ │ block7a_project_… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ top_conv (Conv2D) │ (None, 10, 10, │ 589,824 │ block7b_add[0][0] │ │ │ 1536) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ top_bn │ (None, 10, 10, │ 6,144 │ top_conv[0][0] │ │ (BatchNormalizatio… │ 1536) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ top_activation │ (None, 10, 10, │ 0 │ top_bn[0][0] │ │ (Activation) │ 1536) │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ max_pool │ (None, 1536) │ 0 │ top_activation[0… │ │ (GlobalMaxPooling2… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ batch_normalization │ (None, 1536) │ 6,144 │ max_pool[0][0] │ │ (BatchNormalizatio… │ │ │ │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ dense (Dense) │ (None, 512) │ 786,944 │ batch_normalizat… │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ dropout (Dropout) │ (None, 512) │ 0 │ dense[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ dense_1 (Dense) │ (None, 256) │ 131,328 │ dropout[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ dropout_1 (Dropout) │ (None, 256) │ 0 │ dense_1[0][0] │ ├─────────────────────┼───────────────────┼────────────┼───────────────────┤ │ predictions (Dense) │ (None, 5) │ 1,285 │ dropout_1[0][0] │ └─────────────────────┴───────────────────┴────────────┴───────────────────┘
Total params: 11,709,236 (44.67 MB)
Trainable params: 11,618,861 (44.32 MB)
Non-trainable params: 90,375 (353.03 KB)
Create a custom Keras callback to continue and optionally set LR or halt training
The LR_ASK callback is a convenient callback that allows you to continue training for ask_epoch more epochs or to halt training.
If you elect to continue training for more epochs you are given the option to retain the current learning rate (LR) or to
enter a new value for the learning rate. The form of use is:
ask=LR_ASK(model,epochs, ask_epoch) where:
- model is a string which is the name of your compiled model
- epochs is an integer which is the number of epochs to run specified in model.fit
- ask_epoch is an integer. If ask_epoch is set to a value say 5 then the model will train for 5 epochs.
then the user is ask to enter H to halt training, or enter an inter value. For example if you enter 4
training will continue for 4 more epochs to epoch 9 then you will be queried again. Once you enter an
integer value you are prompted to press ENTER to continue training using the current learning rate
or to enter a new value for the learning rate.
At the end of training the model weights are set to the weights for the epoch that achieved the lowest validation loss
class LR_ASK(keras.callbacks.Callback):
    def __init__ (self, model, epochs,  ask_epoch): # initialization of the callback
        super(LR_ASK, self).__init__()
        self.user_model=model  # Changed from self.model to self.user_model
        self.ask_epoch=ask_epoch
        self.epochs=epochs
        self.ask=True # if True query the user on a specified epoch
        self.lowest_vloss=np.inf
        self.best_weights=self.user_model.get_weights() # Changed to self.user_model
        self.best_epoch=1


    def on_train_begin(self, logs=None): # this runs on the beginning of training
        if self.ask_epoch == 0:
            print('you set ask_epoch = 0, ask_epoch will be set to 1', flush=True)
            self.ask_epoch=1
        if self.ask_epoch >= self.epochs: # you are running for epochs but ask_epoch>epochs
            print('ask_epoch >= epochs, will train for ', epochs, ' epochs', flush=True)
            self.ask=False # do not query the user
        if self.epochs == 1:
            self.ask=False # running only for 1 epoch so do not query user
        else:
            print('Training will proceed until epoch', ask_epoch,' then you will be asked to')
            print(' enter H to halt training or enter an integer for how many more epochs to run then be asked again')
        self.start_time= time.time() # set the time at which training started

    def on_train_end(self, logs=None):   # runs at the end of training
        print('loading model with weights from epoch ', self.best_epoch)
        self.user_model.set_weights(self.best_weights) # Changed to self.user_model
        tr_duration=time.time() - self.start_time   # determine how long the training cycle lasted
        hours = tr_duration // 3600
        minutes = (tr_duration - (hours * 3600)) // 60
        seconds = tr_duration - ((hours * 3600) + (minutes * 60))
        msg = f'training elapsed time was {str(hours)} hours, {minutes:4.1f} minutes, {seconds:4.2f} seconds)'
        print (msg, flush=True) # print out training duration time

    def on_epoch_end(self, epoch, logs=None):  # method runs on the end of each epoch
        v_loss=logs.get('val_loss')  # get the validation loss for this epoch
        if v_loss< self.lowest_vloss:
            self.lowest_vloss=v_loss
            self.best_weights=self.user_model.get_weights() # Changed to self.user_model
            self.best_epoch=epoch + 1
            print (f'\n validation loss of {v_loss:7.4f} is below lowest loss, saving weights from epoch {str(epoch + 1):3s} as best weights')
        else:
            print (f'\n validation loss of {v_loss:7.4f} is above lowest loss of {self.lowest_vloss:7.4f} keeping weights from epoch {str(self.best_epoch)} as best weights')

        if self.ask: # are the conditions right to query the user?
            if epoch + 1 ==self.ask_epoch: # is this epoch the one for quering the user?
                print('\n Enter H to end training or  an integer for the number of additional epochs to run then ask again')
                ans=input()

                if ans == 'H' or ans =='h' or ans == '0': # quit training for these conditions
                    print ('you entered ', ans, ' Training halted on epoch ', epoch+1, ' due to user input\n', flush=True)
                    self.model.stop_training = True # halt training (this self.model is the Keras callback's model)
                else: # user wants to continue training
                    self.ask_epoch += int(ans)
                    if self.ask_epoch > self.epochs:
                        print('\nYou specified maximum epochs of as ', self.epochs, ' cannot train for ', self.ask_epoch, flush =True)
                    else:
                        print ('you entered ', ans, ' Training will continue to epoch ', self.ask_epoch, flush=True)
                        # Fixed: Changed from .lr to .learning_rate
                        lr=float(tf.keras.backend.get_value(self.user_model.optimizer.learning_rate))
                        print(f'current LR is  {lr:7.5f}  hit enter to keep  this LR or enter a new LR')
                        ans=input(' ')
                        if ans =='':
                            print (f'keeping current LR of {lr:7.5f}')
                        else:
                            new_lr=float(ans)
                            # Fixed: Changed from .lr to .learning_rate
                            tf.keras.backend.set_value(self.user_model.optimizer.learning_rate, new_lr)
                            print(' changing LR to ', ans)
Instantiate custom callback
os.makedirs(quarantine_dir, exist_ok=True)

def _decode_and_preprocess_train(path, label):
    p = path.numpy().decode('utf-8')
    try:
        with Image.open(p) as im:
            im = im.convert('RGB')
            im = im.resize((img_size[1], img_size[0]))
            img = np.array(im, dtype=np.uint8)
    except Exception as e:
        # Move problematic file to quarantine to avoid repeated failures
        try:
            dest = os.path.join(quarantine_dir, os.path.basename(p))
            shutil.move(p, dest)
            print('Quarantined bad file:', p)
        except Exception:
            pass
        img = np.zeros((img_size[0], img_size[1], 3), dtype=np.uint8)
    img_pp = albumentations_preprocess(img)
    label_ohe = tf.one_hot(int(label.numpy()), depth=class_count).numpy()
    return img_pp, label_ohe


def _decode_and_preprocess_eval(path, label):
    p = path.numpy().decode('utf-8')
    try:
        with Image.open(p) as im:
            im = im.convert('RGB')
            im = im.resize((img_size[1], img_size[0]))
            img = np.array(im, dtype=np.float32)
    except Exception:
        img = np.zeros((img_size[0], img_size[1], 3), dtype=np.float32)
    img_pp = tf.keras.applications.efficientnet.preprocess_input(img)
    label_ohe = tf.one_hot(int(label.numpy()), depth=class_count).numpy()
    return img_pp, label_ohe

# Rebuild TF datasets using the shape-aware wrappers defined earlier
print('Rebuilding tf.data datasets with robust PIL loaders...')
train_paths = train_df['filepaths'].astype(str).values
train_labels = train_df['labels'].map(class_to_idx).values.astype('int32')
valid_paths = valid_df['filepaths'].astype(str).values
valid_labels = valid_df['labels'].map(class_to_idx).values.astype('int32')
test_paths = test_df['filepaths'].astype(str).values
test_labels = test_df['labels'].map(class_to_idx).values.astype('int32')

train_ds = tf.data.Dataset.from_tensor_slices((train_paths, train_labels))
train_ds = train_ds.shuffle(buffer_size=1000, seed=123)
train_ds = train_ds.map(_py_train, num_parallel_calls=AUTOTUNE)
train_ds = train_ds.batch(batch_size).prefetch(AUTOTUNE)

valid_ds = tf.data.Dataset.from_tensor_slices((valid_paths, valid_labels))
valid_ds = valid_ds.map(_py_eval, num_parallel_calls=AUTOTUNE)
valid_ds = valid_ds.batch(batch_size).prefetch(AUTOTUNE)

test_ds = tf.data.Dataset.from_tensor_slices((test_paths, test_labels))
test_ds = test_ds.map(_py_eval, num_parallel_calls=AUTOTUNE)
test_ds = test_ds.batch(batch_size).prefetch(AUTOTUNE)

# Recompute steps
train_steps = int(np.ceil(len(train_df) / batch_size))
valid_steps = int(np.ceil(len(valid_df) / batch_size))
test_steps = int(np.ceil(len(test_df) / batch_size))

print(f'  Train steps (batches): {train_steps}')
print(f'  Valid steps (batches): {valid_steps}')
print(f'  Test steps (batches): {test_steps}')
Out
Rebuilding tf.data datasets with robust PIL loaders...
  Train steps (batches): 24
  Valid steps (batches): 7
  Test steps (batches): 7
from tensorflow.keras.callbacks import ModelCheckpoint, EarlyStopping, ReduceLROnPlateau

epochs = 150  # Increased for better convergence

# Save best model to Google Drive
checkpoint = ModelCheckpoint(
    '/content/drive/MyDrive/best_cauliflower_model.h5',
    monitor='val_loss',
    save_best_only=True,
    verbose=1,
    mode='min'
)

# Reduce learning rate when validation loss plateaus
reduce_lr = ReduceLROnPlateau(
    monitor='val_loss',
    factor=0.5,  # Reduce LR by half
    patience=4,  # Wait 3 epochs before reducing
    min_lr=1e-7,
    verbose=1,
    mode='min'
)

# Stop early if no improvement
early_stop = EarlyStopping(
    monitor='val_loss',
    patience=12,  # Increased patience for better training
    restore_best_weights=True,
    verbose=1,
    mode='min'
)

callbacks = [checkpoint, reduce_lr, early_stop]
print('✓ Callbacks configured:')
Out
✓ Callbacks configured:
Train the model
Note unlike how you are told it is BETTER to make the base model trainable from the outset
It will converge faster and have a lower validation losss
print('STARTING TRAINING')
print('=' * 80)
print(f'Epochs: {epochs}')
print(f'Batch size: {batch_size}')
print(f'Steps per epoch: {train_steps}')
print(f'Validation steps: {valid_steps}')
print('=' * 80)

history = model.fit(
    x=train_ds,
    epochs=epochs,
    verbose=1,
    callbacks=callbacks,
    validation_data=valid_ds,
    steps_per_epoch=train_steps,
    validation_steps=valid_steps,
    shuffle=False,
    initial_epoch=0
)

print('\n✓ Training completed!')
Out
STARTING TRAINING
================================================================================
Epochs: 150
Batch size: 128
Steps per epoch: 24
Validation steps: 7
================================================================================
Epoch 1/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 7s/step - accuracy: 0.4333 - loss: 3.0678
Epoch 1: val_loss improved from inf to 2.99970, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 440s 9s/step - accuracy: 0.4319 - loss: 3.0780 - val_accuracy: 0.5071 - val_loss: 2.9997 - learning_rate: 5.0000e-04
Epoch 2/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 651ms/step - accuracy: 0.3664 - loss: 2.8209
Epoch 2: val_loss did not improve from 2.99970
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 758ms/step - accuracy: 0.3709 - loss: 2.8078 - val_accuracy: 0.4426 - val_loss: 3.0399 - learning_rate: 5.0000e-04
Epoch 3/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 644ms/step - accuracy: 0.5944 - loss: 2.1612
Epoch 3: val_loss improved from 2.99970 to 2.40780, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 892ms/step - accuracy: 0.5964 - loss: 2.1575 - val_accuracy: 0.5974 - val_loss: 2.4078 - learning_rate: 5.0000e-04
Epoch 4/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 642ms/step - accuracy: 0.6577 - loss: 1.9481
Epoch 4: val_loss improved from 2.40780 to 1.80148, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 819ms/step - accuracy: 0.6594 - loss: 1.9447 - val_accuracy: 0.7432 - val_loss: 1.8015 - learning_rate: 5.0000e-04
Epoch 5/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 645ms/step - accuracy: 0.7470 - loss: 1.7310
Epoch 5: val_loss improved from 1.80148 to 1.40463, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 892ms/step - accuracy: 0.7481 - loss: 1.7291 - val_accuracy: 0.8787 - val_loss: 1.4046 - learning_rate: 5.0000e-04
Epoch 6/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.7524 - loss: 1.7050
Epoch 6: val_loss improved from 1.40463 to 1.27108, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 887ms/step - accuracy: 0.7540 - loss: 1.7018 - val_accuracy: 0.9316 - val_loss: 1.2711 - learning_rate: 5.0000e-04
Epoch 7/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 645ms/step - accuracy: 0.8180 - loss: 1.5672
Epoch 7: val_loss improved from 1.27108 to 1.18150, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 822ms/step - accuracy: 0.8194 - loss: 1.5638 - val_accuracy: 0.9626 - val_loss: 1.1815 - learning_rate: 5.0000e-04
Epoch 8/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.8405 - loss: 1.5180
Epoch 8: val_loss improved from 1.18150 to 1.16558, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 896ms/step - accuracy: 0.8412 - loss: 1.5156 - val_accuracy: 0.9665 - val_loss: 1.1656 - learning_rate: 5.0000e-04
Epoch 9/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 640ms/step - accuracy: 0.8709 - loss: 1.4390
Epoch 9: val_loss improved from 1.16558 to 1.12696, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 879ms/step - accuracy: 0.8719 - loss: 1.4365 - val_accuracy: 0.9794 - val_loss: 1.1270 - learning_rate: 5.0000e-04
Epoch 10/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 657ms/step - accuracy: 0.8940 - loss: 1.3669
Epoch 10: val_loss improved from 1.12696 to 1.11380, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 834ms/step - accuracy: 0.8945 - loss: 1.3657 - val_accuracy: 0.9845 - val_loss: 1.1138 - learning_rate: 5.0000e-04
Epoch 11/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9018 - loss: 1.3218
Epoch 11: val_loss improved from 1.11380 to 1.10739, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 893ms/step - accuracy: 0.9025 - loss: 1.3205 - val_accuracy: 0.9819 - val_loss: 1.1074 - learning_rate: 5.0000e-04
Epoch 12/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 638ms/step - accuracy: 0.9264 - loss: 1.2684
Epoch 12: val_loss improved from 1.10739 to 1.09452, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 826ms/step - accuracy: 0.9268 - loss: 1.2677 - val_accuracy: 0.9884 - val_loss: 1.0945 - learning_rate: 5.0000e-04
Epoch 13/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 645ms/step - accuracy: 0.9310 - loss: 1.2420
Epoch 13: val_loss improved from 1.09452 to 1.09037, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 837ms/step - accuracy: 0.9315 - loss: 1.2409 - val_accuracy: 0.9884 - val_loss: 1.0904 - learning_rate: 5.0000e-04
Epoch 14/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 641ms/step - accuracy: 0.9418 - loss: 1.2119
Epoch 14: val_loss improved from 1.09037 to 1.08318, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 886ms/step - accuracy: 0.9421 - loss: 1.2114 - val_accuracy: 0.9897 - val_loss: 1.0832 - learning_rate: 5.0000e-04
Epoch 15/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 636ms/step - accuracy: 0.9601 - loss: 1.1633
Epoch 15: val_loss improved from 1.08318 to 1.07057, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 19s 814ms/step - accuracy: 0.9603 - loss: 1.1629 - val_accuracy: 0.9935 - val_loss: 1.0706 - learning_rate: 5.0000e-04
Epoch 16/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9604 - loss: 1.1637
Epoch 16: val_loss improved from 1.07057 to 1.06280, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 882ms/step - accuracy: 0.9607 - loss: 1.1630 - val_accuracy: 0.9923 - val_loss: 1.0628 - learning_rate: 5.0000e-04
Epoch 17/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 638ms/step - accuracy: 0.9661 - loss: 1.1505
Epoch 17: val_loss improved from 1.06280 to 1.06224, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 890ms/step - accuracy: 0.9663 - loss: 1.1501 - val_accuracy: 0.9897 - val_loss: 1.0622 - learning_rate: 5.0000e-04
Epoch 18/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 638ms/step - accuracy: 0.9764 - loss: 1.1157
Epoch 18: val_loss improved from 1.06224 to 1.05840, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 888ms/step - accuracy: 0.9764 - loss: 1.1156 - val_accuracy: 0.9910 - val_loss: 1.0584 - learning_rate: 5.0000e-04
Epoch 19/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 649ms/step - accuracy: 0.9729 - loss: 1.1051
Epoch 19: val_loss improved from 1.05840 to 1.05251, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 890ms/step - accuracy: 0.9728 - loss: 1.1053 - val_accuracy: 0.9910 - val_loss: 1.0525 - learning_rate: 5.0000e-04
Epoch 20/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 645ms/step - accuracy: 0.9612 - loss: 1.1271
Epoch 20: val_loss improved from 1.05251 to 1.04213, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 881ms/step - accuracy: 0.9614 - loss: 1.1266 - val_accuracy: 0.9910 - val_loss: 1.0421 - learning_rate: 5.0000e-04
Epoch 21/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9748 - loss: 1.0898
Epoch 21: val_loss improved from 1.04213 to 1.03727, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 820ms/step - accuracy: 0.9749 - loss: 1.0898 - val_accuracy: 0.9948 - val_loss: 1.0373 - learning_rate: 5.0000e-04
Epoch 22/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 645ms/step - accuracy: 0.9801 - loss: 1.0834
Epoch 22: val_loss improved from 1.03727 to 1.02597, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 22s 921ms/step - accuracy: 0.9802 - loss: 1.0831 - val_accuracy: 0.9987 - val_loss: 1.0260 - learning_rate: 5.0000e-04
Epoch 23/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9727 - loss: 1.0938
Epoch 23: val_loss did not improve from 1.02597
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 748ms/step - accuracy: 0.9729 - loss: 1.0932 - val_accuracy: 0.9910 - val_loss: 1.0357 - learning_rate: 5.0000e-04
Epoch 24/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 637ms/step - accuracy: 0.9844 - loss: 1.0551
Epoch 24: val_loss improved from 1.02597 to 1.01682, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 882ms/step - accuracy: 0.9844 - loss: 1.0550 - val_accuracy: 0.9974 - val_loss: 1.0168 - learning_rate: 5.0000e-04
Epoch 25/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 650ms/step - accuracy: 0.9896 - loss: 1.0381
Epoch 25: val_loss improved from 1.01682 to 1.01030, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 896ms/step - accuracy: 0.9895 - loss: 1.0383 - val_accuracy: 0.9974 - val_loss: 1.0103 - learning_rate: 5.0000e-04
Epoch 26/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 647ms/step - accuracy: 0.9875 - loss: 1.0463
Epoch 26: val_loss improved from 1.01030 to 1.00553, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 833ms/step - accuracy: 0.9875 - loss: 1.0460 - val_accuracy: 0.9935 - val_loss: 1.0055 - learning_rate: 5.0000e-04
Epoch 27/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 640ms/step - accuracy: 0.9892 - loss: 1.0331
Epoch 27: val_loss improved from 1.00553 to 1.00217, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 877ms/step - accuracy: 0.9891 - loss: 1.0334 - val_accuracy: 0.9935 - val_loss: 1.0022 - learning_rate: 5.0000e-04
Epoch 28/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9892 - loss: 1.0172
Epoch 28: val_loss improved from 1.00217 to 0.99440, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 824ms/step - accuracy: 0.9891 - loss: 1.0172 - val_accuracy: 0.9961 - val_loss: 0.9944 - learning_rate: 5.0000e-04
Epoch 29/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9931 - loss: 1.0092
Epoch 29: val_loss improved from 0.99440 to 0.99361, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 823ms/step - accuracy: 0.9930 - loss: 1.0093 - val_accuracy: 0.9948 - val_loss: 0.9936 - learning_rate: 5.0000e-04
Epoch 30/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9854 - loss: 1.0231
Epoch 30: val_loss improved from 0.99361 to 0.98258, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 883ms/step - accuracy: 0.9855 - loss: 1.0226 - val_accuracy: 0.9987 - val_loss: 0.9826 - learning_rate: 5.0000e-04
Epoch 31/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 648ms/step - accuracy: 0.9857 - loss: 1.0171
Epoch 31: val_loss improved from 0.98258 to 0.97777, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 836ms/step - accuracy: 0.9857 - loss: 1.0168 - val_accuracy: 0.9923 - val_loss: 0.9778 - learning_rate: 5.0000e-04
Epoch 32/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9929 - loss: 0.9873
Epoch 32: val_loss did not improve from 0.97777
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 743ms/step - accuracy: 0.9928 - loss: 0.9873 - val_accuracy: 0.9910 - val_loss: 0.9889 - learning_rate: 5.0000e-04
Epoch 33/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 637ms/step - accuracy: 0.9881 - loss: 0.9826
Epoch 33: val_loss did not improve from 0.97777
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 741ms/step - accuracy: 0.9881 - loss: 0.9824 - val_accuracy: 0.9897 - val_loss: 0.9798 - learning_rate: 5.0000e-04
Epoch 34/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 638ms/step - accuracy: 0.9911 - loss: 0.9794
Epoch 34: val_loss improved from 0.97777 to 0.97111, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 881ms/step - accuracy: 0.9911 - loss: 0.9793 - val_accuracy: 0.9923 - val_loss: 0.9711 - learning_rate: 5.0000e-04
Epoch 35/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9916 - loss: 0.9654
Epoch 35: val_loss improved from 0.97111 to 0.95788, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 821ms/step - accuracy: 0.9916 - loss: 0.9653 - val_accuracy: 0.9948 - val_loss: 0.9579 - learning_rate: 5.0000e-04
Epoch 36/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 642ms/step - accuracy: 0.9881 - loss: 0.9717
Epoch 36: val_loss improved from 0.95788 to 0.94274, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 821ms/step - accuracy: 0.9881 - loss: 0.9716 - val_accuracy: 0.9961 - val_loss: 0.9427 - learning_rate: 5.0000e-04
Epoch 37/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 648ms/step - accuracy: 0.9923 - loss: 0.9539
Epoch 37: val_loss improved from 0.94274 to 0.93951, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 827ms/step - accuracy: 0.9923 - loss: 0.9539 - val_accuracy: 0.9935 - val_loss: 0.9395 - learning_rate: 5.0000e-04
Epoch 38/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 640ms/step - accuracy: 0.9872 - loss: 0.9592
Epoch 38: val_loss improved from 0.93951 to 0.93673, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 888ms/step - accuracy: 0.9873 - loss: 0.9590 - val_accuracy: 0.9935 - val_loss: 0.9367 - learning_rate: 5.0000e-04
Epoch 39/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 648ms/step - accuracy: 0.9913 - loss: 0.9408
Epoch 39: val_loss improved from 0.93673 to 0.92579, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 828ms/step - accuracy: 0.9913 - loss: 0.9408 - val_accuracy: 0.9961 - val_loss: 0.9258 - learning_rate: 5.0000e-04
Epoch 40/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 636ms/step - accuracy: 0.9916 - loss: 0.9366
Epoch 40: val_loss improved from 0.92579 to 0.92142, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 885ms/step - accuracy: 0.9915 - loss: 0.9366 - val_accuracy: 0.9935 - val_loss: 0.9214 - learning_rate: 5.0000e-04
Epoch 41/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 651ms/step - accuracy: 0.9964 - loss: 0.9246
Epoch 41: val_loss did not improve from 0.92142
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 753ms/step - accuracy: 0.9964 - loss: 0.9246 - val_accuracy: 0.9897 - val_loss: 0.9320 - learning_rate: 5.0000e-04
Epoch 42/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9924 - loss: 0.9244
Epoch 42: val_loss improved from 0.92142 to 0.90841, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 893ms/step - accuracy: 0.9924 - loss: 0.9242 - val_accuracy: 0.9935 - val_loss: 0.9084 - learning_rate: 5.0000e-04
Epoch 43/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 640ms/step - accuracy: 0.9947 - loss: 0.9066
Epoch 43: val_loss improved from 0.90841 to 0.89584, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 875ms/step - accuracy: 0.9947 - loss: 0.9067 - val_accuracy: 0.9948 - val_loss: 0.8958 - learning_rate: 5.0000e-04
Epoch 44/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 633ms/step - accuracy: 0.9957 - loss: 0.9014
Epoch 44: val_loss improved from 0.89584 to 0.89436, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 868ms/step - accuracy: 0.9956 - loss: 0.9015 - val_accuracy: 0.9923 - val_loss: 0.8944 - learning_rate: 5.0000e-04
Epoch 45/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9925 - loss: 0.8979
Epoch 45: val_loss improved from 0.89436 to 0.89243, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 873ms/step - accuracy: 0.9926 - loss: 0.8978 - val_accuracy: 0.9923 - val_loss: 0.8924 - learning_rate: 5.0000e-04
Epoch 46/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 633ms/step - accuracy: 0.9959 - loss: 0.8852
Epoch 46: val_loss improved from 0.89243 to 0.87678, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 869ms/step - accuracy: 0.9959 - loss: 0.8853 - val_accuracy: 0.9948 - val_loss: 0.8768 - learning_rate: 5.0000e-04
Epoch 47/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 634ms/step - accuracy: 0.9940 - loss: 0.8782
Epoch 47: val_loss improved from 0.87678 to 0.86299, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 19s 810ms/step - accuracy: 0.9940 - loss: 0.8781 - val_accuracy: 0.9974 - val_loss: 0.8630 - learning_rate: 5.0000e-04
Epoch 48/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 636ms/step - accuracy: 0.9957 - loss: 0.8707
Epoch 48: val_loss did not improve from 0.86299
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 738ms/step - accuracy: 0.9957 - loss: 0.8706 - val_accuracy: 0.9948 - val_loss: 0.8677 - learning_rate: 5.0000e-04
Epoch 49/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 631ms/step - accuracy: 0.9950 - loss: 0.8620
Epoch 49: val_loss improved from 0.86299 to 0.85525, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 876ms/step - accuracy: 0.9951 - loss: 0.8619 - val_accuracy: 0.9935 - val_loss: 0.8553 - learning_rate: 5.0000e-04
Epoch 50/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9972 - loss: 0.8511
Epoch 50: val_loss improved from 0.85525 to 0.84682, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 868ms/step - accuracy: 0.9972 - loss: 0.8510 - val_accuracy: 0.9961 - val_loss: 0.8468 - learning_rate: 5.0000e-04
Epoch 51/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9979 - loss: 0.8444
Epoch 51: val_loss improved from 0.84682 to 0.83883, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 872ms/step - accuracy: 0.9978 - loss: 0.8443 - val_accuracy: 0.9961 - val_loss: 0.8388 - learning_rate: 5.0000e-04
Epoch 52/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 634ms/step - accuracy: 0.9976 - loss: 0.8332
Epoch 52: val_loss improved from 0.83883 to 0.83020, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 19s 811ms/step - accuracy: 0.9976 - loss: 0.8332 - val_accuracy: 0.9935 - val_loss: 0.8302 - learning_rate: 5.0000e-04
Epoch 53/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9976 - loss: 0.8267
Epoch 53: val_loss improved from 0.83020 to 0.82840, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 873ms/step - accuracy: 0.9976 - loss: 0.8267 - val_accuracy: 0.9961 - val_loss: 0.8284 - learning_rate: 5.0000e-04
Epoch 54/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9928 - loss: 0.8248
Epoch 54: val_loss improved from 0.82840 to 0.80889, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 871ms/step - accuracy: 0.9929 - loss: 0.8248 - val_accuracy: 0.9974 - val_loss: 0.8089 - learning_rate: 5.0000e-04
Epoch 55/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 634ms/step - accuracy: 0.9967 - loss: 0.8102
Epoch 55: val_loss did not improve from 0.80889
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 738ms/step - accuracy: 0.9967 - loss: 0.8101 - val_accuracy: 0.9935 - val_loss: 0.8188 - learning_rate: 5.0000e-04
Epoch 56/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9961 - loss: 0.8080
Epoch 56: val_loss improved from 0.80889 to 0.79353, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 892ms/step - accuracy: 0.9961 - loss: 0.8079 - val_accuracy: 0.9974 - val_loss: 0.7935 - learning_rate: 5.0000e-04
Epoch 57/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 631ms/step - accuracy: 0.9972 - loss: 0.7980
Epoch 57: val_loss did not improve from 0.79353
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 734ms/step - accuracy: 0.9972 - loss: 0.7980 - val_accuracy: 0.9961 - val_loss: 0.7942 - learning_rate: 5.0000e-04
Epoch 58/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 630ms/step - accuracy: 0.9943 - loss: 0.7894
Epoch 58: val_loss improved from 0.79353 to 0.78713, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 880ms/step - accuracy: 0.9943 - loss: 0.7892 - val_accuracy: 0.9935 - val_loss: 0.7871 - learning_rate: 5.0000e-04
Epoch 59/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 633ms/step - accuracy: 0.9942 - loss: 0.7827
Epoch 59: val_loss improved from 0.78713 to 0.77502, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 877ms/step - accuracy: 0.9942 - loss: 0.7826 - val_accuracy: 0.9974 - val_loss: 0.7750 - learning_rate: 5.0000e-04
Epoch 60/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 631ms/step - accuracy: 0.9994 - loss: 0.7655
Epoch 60: val_loss improved from 0.77502 to 0.76808, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 19s 808ms/step - accuracy: 0.9993 - loss: 0.7656 - val_accuracy: 0.9961 - val_loss: 0.7681 - learning_rate: 5.0000e-04
Epoch 61/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 632ms/step - accuracy: 0.9966 - loss: 0.7650
Epoch 61: val_loss improved from 0.76808 to 0.75806, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 19s 810ms/step - accuracy: 0.9966 - loss: 0.7648 - val_accuracy: 0.9987 - val_loss: 0.7581 - learning_rate: 5.0000e-04
Epoch 62/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 634ms/step - accuracy: 0.9956 - loss: 0.7558
Epoch 62: val_loss improved from 0.75806 to 0.75400, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 19s 810ms/step - accuracy: 0.9956 - loss: 0.7558 - val_accuracy: 0.9948 - val_loss: 0.7540 - learning_rate: 5.0000e-04
Epoch 63/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 632ms/step - accuracy: 0.9963 - loss: 0.7483
Epoch 63: val_loss improved from 0.75400 to 0.73819, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 863ms/step - accuracy: 0.9963 - loss: 0.7484 - val_accuracy: 0.9974 - val_loss: 0.7382 - learning_rate: 5.0000e-04
Epoch 64/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 633ms/step - accuracy: 0.9942 - loss: 0.7453
Epoch 64: val_loss improved from 0.73819 to 0.73649, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 19s 813ms/step - accuracy: 0.9942 - loss: 0.7451 - val_accuracy: 0.9974 - val_loss: 0.7365 - learning_rate: 5.0000e-04
Epoch 65/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 629ms/step - accuracy: 0.9985 - loss: 0.7251
Epoch 65: val_loss improved from 0.73649 to 0.72561, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 19s 807ms/step - accuracy: 0.9985 - loss: 0.7251 - val_accuracy: 0.9974 - val_loss: 0.7256 - learning_rate: 5.0000e-04
Epoch 66/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 634ms/step - accuracy: 0.9967 - loss: 0.7187
Epoch 66: val_loss improved from 0.72561 to 0.71785, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 875ms/step - accuracy: 0.9967 - loss: 0.7187 - val_accuracy: 0.9961 - val_loss: 0.7178 - learning_rate: 5.0000e-04
Epoch 67/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 632ms/step - accuracy: 0.9955 - loss: 0.7187
Epoch 67: val_loss improved from 0.71785 to 0.71320, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 868ms/step - accuracy: 0.9955 - loss: 0.7186 - val_accuracy: 0.9935 - val_loss: 0.7132 - learning_rate: 5.0000e-04
Epoch 68/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9977 - loss: 0.7042
Epoch 68: val_loss improved from 0.71320 to 0.69843, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 19s 809ms/step - accuracy: 0.9977 - loss: 0.7041 - val_accuracy: 0.9961 - val_loss: 0.6984 - learning_rate: 5.0000e-04
Epoch 69/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 633ms/step - accuracy: 0.9964 - loss: 0.6960
Epoch 69: val_loss did not improve from 0.69843
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 737ms/step - accuracy: 0.9964 - loss: 0.6959 - val_accuracy: 0.9935 - val_loss: 0.6994 - learning_rate: 5.0000e-04
Epoch 70/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 631ms/step - accuracy: 0.9952 - loss: 0.6909
Epoch 70: val_loss improved from 0.69843 to 0.68642, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 874ms/step - accuracy: 0.9952 - loss: 0.6907 - val_accuracy: 0.9935 - val_loss: 0.6864 - learning_rate: 5.0000e-04
Epoch 71/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9979 - loss: 0.6760
Epoch 71: val_loss improved from 0.68642 to 0.67345, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 19s 815ms/step - accuracy: 0.9978 - loss: 0.6760 - val_accuracy: 0.9974 - val_loss: 0.6734 - learning_rate: 5.0000e-04
Epoch 72/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 646ms/step - accuracy: 0.9981 - loss: 0.6671
Epoch 72: val_loss improved from 0.67345 to 0.66849, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 822ms/step - accuracy: 0.9980 - loss: 0.6670 - val_accuracy: 0.9948 - val_loss: 0.6685 - learning_rate: 5.0000e-04
Epoch 73/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9989 - loss: 0.6544
Epoch 73: val_loss did not improve from 0.66849
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 737ms/step - accuracy: 0.9989 - loss: 0.6543 - val_accuracy: 0.9923 - val_loss: 0.6758 - learning_rate: 5.0000e-04
Epoch 74/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 627ms/step - accuracy: 0.9976 - loss: 0.6519
Epoch 74: val_loss improved from 0.66849 to 0.65017, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 872ms/step - accuracy: 0.9977 - loss: 0.6518 - val_accuracy: 0.9961 - val_loss: 0.6502 - learning_rate: 5.0000e-04
Epoch 75/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 644ms/step - accuracy: 0.9959 - loss: 0.6465
Epoch 75: val_loss did not improve from 0.65017
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 747ms/step - accuracy: 0.9960 - loss: 0.6463 - val_accuracy: 0.9910 - val_loss: 0.6533 - learning_rate: 5.0000e-04
Epoch 76/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 627ms/step - accuracy: 0.9986 - loss: 0.6287
Epoch 76: val_loss did not improve from 0.65017
24/24 ━━━━━━━━━━━━━━━━━━━━ 17s 730ms/step - accuracy: 0.9986 - loss: 0.6288 - val_accuracy: 0.9884 - val_loss: 0.6547 - learning_rate: 5.0000e-04
Epoch 77/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 627ms/step - accuracy: 0.9963 - loss: 0.6290
Epoch 77: val_loss improved from 0.65017 to 0.62182, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 874ms/step - accuracy: 0.9963 - loss: 0.6288 - val_accuracy: 0.9948 - val_loss: 0.6218 - learning_rate: 5.0000e-04
Epoch 78/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 634ms/step - accuracy: 0.9979 - loss: 0.6143
Epoch 78: val_loss improved from 0.62182 to 0.61170, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 19s 812ms/step - accuracy: 0.9979 - loss: 0.6143 - val_accuracy: 0.9961 - val_loss: 0.6117 - learning_rate: 5.0000e-04
Epoch 79/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 634ms/step - accuracy: 0.9994 - loss: 0.6036
Epoch 79: val_loss improved from 0.61170 to 0.60763, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 868ms/step - accuracy: 0.9994 - loss: 0.6035 - val_accuracy: 0.9974 - val_loss: 0.6076 - learning_rate: 5.0000e-04
Epoch 80/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9962 - loss: 0.6007
Epoch 80: val_loss improved from 0.60763 to 0.59148, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 873ms/step - accuracy: 0.9962 - loss: 0.6007 - val_accuracy: 0.9974 - val_loss: 0.5915 - learning_rate: 5.0000e-04
Epoch 81/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9978 - loss: 0.5901
Epoch 81: val_loss did not improve from 0.59148
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 738ms/step - accuracy: 0.9977 - loss: 0.5901 - val_accuracy: 0.9935 - val_loss: 0.6017 - learning_rate: 5.0000e-04
Epoch 82/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 630ms/step - accuracy: 0.9986 - loss: 0.5793
Epoch 82: val_loss improved from 0.59148 to 0.57572, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 876ms/step - accuracy: 0.9985 - loss: 0.5794 - val_accuracy: 0.9961 - val_loss: 0.5757 - learning_rate: 5.0000e-04
Epoch 83/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 628ms/step - accuracy: 0.9989 - loss: 0.5695
Epoch 83: val_loss did not improve from 0.57572
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 731ms/step - accuracy: 0.9989 - loss: 0.5695 - val_accuracy: 0.9948 - val_loss: 0.5809 - learning_rate: 5.0000e-04
Epoch 84/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 628ms/step - accuracy: 0.9963 - loss: 0.5645
Epoch 84: val_loss improved from 0.57572 to 0.57188, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 904ms/step - accuracy: 0.9963 - loss: 0.5644 - val_accuracy: 0.9923 - val_loss: 0.5719 - learning_rate: 5.0000e-04
Epoch 85/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 629ms/step - accuracy: 0.9977 - loss: 0.5552
Epoch 85: val_loss improved from 0.57188 to 0.55612, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 862ms/step - accuracy: 0.9976 - loss: 0.5552 - val_accuracy: 0.9948 - val_loss: 0.5561 - learning_rate: 5.0000e-04
Epoch 86/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 637ms/step - accuracy: 0.9988 - loss: 0.5453
Epoch 86: val_loss improved from 0.55612 to 0.54696, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 875ms/step - accuracy: 0.9988 - loss: 0.5453 - val_accuracy: 0.9948 - val_loss: 0.5470 - learning_rate: 5.0000e-04
Epoch 87/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9986 - loss: 0.5359
Epoch 87: val_loss improved from 0.54696 to 0.53636, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 881ms/step - accuracy: 0.9986 - loss: 0.5358 - val_accuracy: 0.9961 - val_loss: 0.5364 - learning_rate: 5.0000e-04
Epoch 88/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 647ms/step - accuracy: 0.9985 - loss: 0.5276
Epoch 88: val_loss improved from 0.53636 to 0.52795, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 888ms/step - accuracy: 0.9985 - loss: 0.5275 - val_accuracy: 0.9974 - val_loss: 0.5279 - learning_rate: 5.0000e-04
Epoch 89/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 644ms/step - accuracy: 0.9999 - loss: 0.5163
Epoch 89: val_loss improved from 0.52795 to 0.52327, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 889ms/step - accuracy: 0.9999 - loss: 0.5162 - val_accuracy: 0.9961 - val_loss: 0.5233 - learning_rate: 5.0000e-04
Epoch 90/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 646ms/step - accuracy: 0.9960 - loss: 0.5148
Epoch 90: val_loss improved from 0.52327 to 0.51487, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 826ms/step - accuracy: 0.9961 - loss: 0.5147 - val_accuracy: 0.9961 - val_loss: 0.5149 - learning_rate: 5.0000e-04
Epoch 91/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 637ms/step - accuracy: 0.9991 - loss: 0.5001
Epoch 91: val_loss improved from 0.51487 to 0.51086, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 819ms/step - accuracy: 0.9991 - loss: 0.5000 - val_accuracy: 0.9935 - val_loss: 0.5109 - learning_rate: 5.0000e-04
Epoch 92/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 642ms/step - accuracy: 0.9982 - loss: 0.4945
Epoch 92: val_loss improved from 0.51086 to 0.50982, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 882ms/step - accuracy: 0.9982 - loss: 0.4945 - val_accuracy: 0.9923 - val_loss: 0.5098 - learning_rate: 5.0000e-04
Epoch 93/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 641ms/step - accuracy: 0.9996 - loss: 0.4865
Epoch 93: val_loss improved from 0.50982 to 0.50296, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 825ms/step - accuracy: 0.9996 - loss: 0.4864 - val_accuracy: 0.9910 - val_loss: 0.5030 - learning_rate: 5.0000e-04
Epoch 94/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 638ms/step - accuracy: 1.0000 - loss: 0.4760
Epoch 94: val_loss improved from 0.50296 to 0.49139, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 887ms/step - accuracy: 1.0000 - loss: 0.4759 - val_accuracy: 0.9935 - val_loss: 0.4914 - learning_rate: 5.0000e-04
Epoch 95/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 637ms/step - accuracy: 0.9977 - loss: 0.4693
Epoch 95: val_loss improved from 0.49139 to 0.48243, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 880ms/step - accuracy: 0.9977 - loss: 0.4692 - val_accuracy: 0.9935 - val_loss: 0.4824 - learning_rate: 5.0000e-04
Epoch 96/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 638ms/step - accuracy: 0.9981 - loss: 0.4634
Epoch 96: val_loss improved from 0.48243 to 0.47229, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 891ms/step - accuracy: 0.9981 - loss: 0.4634 - val_accuracy: 0.9935 - val_loss: 0.4723 - learning_rate: 5.0000e-04
Epoch 97/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 641ms/step - accuracy: 0.9990 - loss: 0.4529
Epoch 97: val_loss improved from 0.47229 to 0.45122, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 880ms/step - accuracy: 0.9990 - loss: 0.4528 - val_accuracy: 0.9948 - val_loss: 0.4512 - learning_rate: 5.0000e-04
Epoch 98/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 642ms/step - accuracy: 0.9975 - loss: 0.4485
Epoch 98: val_loss did not improve from 0.45122
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 745ms/step - accuracy: 0.9975 - loss: 0.4484 - val_accuracy: 0.9910 - val_loss: 0.4778 - learning_rate: 5.0000e-04
Epoch 99/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 636ms/step - accuracy: 0.9984 - loss: 0.4402
Epoch 99: val_loss did not improve from 0.45122
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 742ms/step - accuracy: 0.9984 - loss: 0.4401 - val_accuracy: 0.9910 - val_loss: 0.4646 - learning_rate: 5.0000e-04
Epoch 100/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 636ms/step - accuracy: 0.9962 - loss: 0.4374
Epoch 100: val_loss did not improve from 0.45122
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 741ms/step - accuracy: 0.9962 - loss: 0.4371 - val_accuracy: 0.9910 - val_loss: 0.4657 - learning_rate: 5.0000e-04
Epoch 101/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 633ms/step - accuracy: 0.9992 - loss: 0.4205
Epoch 101: val_loss improved from 0.45122 to 0.43177, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 877ms/step - accuracy: 0.9992 - loss: 0.4205 - val_accuracy: 0.9923 - val_loss: 0.4318 - learning_rate: 5.0000e-04
Epoch 102/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 638ms/step - accuracy: 0.9969 - loss: 0.4167
Epoch 102: val_loss did not improve from 0.43177
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 741ms/step - accuracy: 0.9970 - loss: 0.4165 - val_accuracy: 0.9910 - val_loss: 0.4391 - learning_rate: 5.0000e-04
Epoch 103/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 637ms/step - accuracy: 0.9992 - loss: 0.4052
Epoch 103: val_loss improved from 0.43177 to 0.40880, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 889ms/step - accuracy: 0.9992 - loss: 0.4052 - val_accuracy: 0.9948 - val_loss: 0.4088 - learning_rate: 5.0000e-04
Epoch 104/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9970 - loss: 0.4042
Epoch 104: val_loss did not improve from 0.40880
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 739ms/step - accuracy: 0.9970 - loss: 0.4042 - val_accuracy: 0.9923 - val_loss: 0.4174 - learning_rate: 5.0000e-04
Epoch 105/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 637ms/step - accuracy: 0.9992 - loss: 0.3907
Epoch 105: val_loss improved from 0.40880 to 0.39847, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 885ms/step - accuracy: 0.9992 - loss: 0.3906 - val_accuracy: 0.9935 - val_loss: 0.3985 - learning_rate: 5.0000e-04
Epoch 106/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9982 - loss: 0.3843
Epoch 106: val_loss improved from 0.39847 to 0.39325, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 823ms/step - accuracy: 0.9982 - loss: 0.3843 - val_accuracy: 0.9948 - val_loss: 0.3933 - learning_rate: 5.0000e-04
Epoch 107/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 641ms/step - accuracy: 0.9968 - loss: 0.3804
Epoch 107: val_loss improved from 0.39325 to 0.38860, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 818ms/step - accuracy: 0.9968 - loss: 0.3803 - val_accuracy: 0.9948 - val_loss: 0.3886 - learning_rate: 5.0000e-04
Epoch 108/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 636ms/step - accuracy: 0.9992 - loss: 0.3710
Epoch 108: val_loss improved from 0.38860 to 0.37875, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 884ms/step - accuracy: 0.9991 - loss: 0.3709 - val_accuracy: 0.9948 - val_loss: 0.3788 - learning_rate: 5.0000e-04
Epoch 109/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 647ms/step - accuracy: 0.9990 - loss: 0.3621
Epoch 109: val_loss improved from 0.37875 to 0.37353, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 891ms/step - accuracy: 0.9990 - loss: 0.3621 - val_accuracy: 0.9961 - val_loss: 0.3735 - learning_rate: 5.0000e-04
Epoch 110/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 636ms/step - accuracy: 0.9996 - loss: 0.3536
Epoch 110: val_loss did not improve from 0.37353
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 743ms/step - accuracy: 0.9995 - loss: 0.3536 - val_accuracy: 0.9948 - val_loss: 0.3752 - learning_rate: 5.0000e-04
Epoch 111/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9975 - loss: 0.3509
Epoch 111: val_loss improved from 0.37353 to 0.36717, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 886ms/step - accuracy: 0.9976 - loss: 0.3508 - val_accuracy: 0.9935 - val_loss: 0.3672 - learning_rate: 5.0000e-04
Epoch 112/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9983 - loss: 0.3423
Epoch 112: val_loss improved from 0.36717 to 0.35028, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 876ms/step - accuracy: 0.9983 - loss: 0.3422 - val_accuracy: 0.9935 - val_loss: 0.3503 - learning_rate: 5.0000e-04
Epoch 113/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 641ms/step - accuracy: 0.9995 - loss: 0.3337
Epoch 113: val_loss did not improve from 0.35028
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 744ms/step - accuracy: 0.9994 - loss: 0.3338 - val_accuracy: 0.9948 - val_loss: 0.3555 - learning_rate: 5.0000e-04
Epoch 114/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9986 - loss: 0.3371
Epoch 114: val_loss improved from 0.35028 to 0.33313, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 902ms/step - accuracy: 0.9986 - loss: 0.3368 - val_accuracy: 0.9948 - val_loss: 0.3331 - learning_rate: 5.0000e-04
Epoch 115/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9991 - loss: 0.3209
Epoch 115: val_loss improved from 0.33313 to 0.32908, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 824ms/step - accuracy: 0.9991 - loss: 0.3209 - val_accuracy: 0.9961 - val_loss: 0.3291 - learning_rate: 5.0000e-04
Epoch 116/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 638ms/step - accuracy: 0.9978 - loss: 0.3147
Epoch 116: val_loss improved from 0.32908 to 0.32053, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 892ms/step - accuracy: 0.9978 - loss: 0.3146 - val_accuracy: 0.9961 - val_loss: 0.3205 - learning_rate: 5.0000e-04
Epoch 117/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 636ms/step - accuracy: 0.9975 - loss: 0.3117
Epoch 117: val_loss improved from 0.32053 to 0.31414, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 820ms/step - accuracy: 0.9975 - loss: 0.3116 - val_accuracy: 0.9961 - val_loss: 0.3141 - learning_rate: 5.0000e-04
Epoch 118/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 646ms/step - accuracy: 0.9993 - loss: 0.3011
Epoch 118: val_loss improved from 0.31414 to 0.30237, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 895ms/step - accuracy: 0.9992 - loss: 0.3011 - val_accuracy: 0.9974 - val_loss: 0.3024 - learning_rate: 5.0000e-04
Epoch 119/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 645ms/step - accuracy: 0.9993 - loss: 0.2954
Epoch 119: val_loss improved from 0.30237 to 0.29839, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 882ms/step - accuracy: 0.9993 - loss: 0.2954 - val_accuracy: 0.9961 - val_loss: 0.2984 - learning_rate: 5.0000e-04
Epoch 120/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 644ms/step - accuracy: 0.9990 - loss: 0.2896
Epoch 120: val_loss improved from 0.29839 to 0.28987, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 894ms/step - accuracy: 0.9990 - loss: 0.2896 - val_accuracy: 0.9961 - val_loss: 0.2899 - learning_rate: 5.0000e-04
Epoch 121/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9990 - loss: 0.2827
Epoch 121: val_loss improved from 0.28987 to 0.28499, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 886ms/step - accuracy: 0.9990 - loss: 0.2827 - val_accuracy: 0.9961 - val_loss: 0.2850 - learning_rate: 5.0000e-04
Epoch 122/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 641ms/step - accuracy: 0.9992 - loss: 0.2761
Epoch 122: val_loss improved from 0.28499 to 0.28144, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 880ms/step - accuracy: 0.9992 - loss: 0.2761 - val_accuracy: 0.9961 - val_loss: 0.2814 - learning_rate: 5.0000e-04
Epoch 123/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9982 - loss: 0.2712
Epoch 123: val_loss improved from 0.28144 to 0.27900, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 826ms/step - accuracy: 0.9982 - loss: 0.2711 - val_accuracy: 0.9948 - val_loss: 0.2790 - learning_rate: 5.0000e-04
Epoch 124/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9984 - loss: 0.2656
Epoch 124: val_loss improved from 0.27900 to 0.26647, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 884ms/step - accuracy: 0.9984 - loss: 0.2655 - val_accuracy: 0.9961 - val_loss: 0.2665 - learning_rate: 5.0000e-04
Epoch 125/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9998 - loss: 0.2577
Epoch 125: val_loss improved from 0.26647 to 0.25864, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 817ms/step - accuracy: 0.9998 - loss: 0.2577 - val_accuracy: 0.9961 - val_loss: 0.2586 - learning_rate: 5.0000e-04
Epoch 126/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 641ms/step - accuracy: 0.9991 - loss: 0.2538
Epoch 126: val_loss improved from 0.25864 to 0.25504, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 22s 917ms/step - accuracy: 0.9990 - loss: 0.2538 - val_accuracy: 0.9974 - val_loss: 0.2550 - learning_rate: 5.0000e-04
Epoch 127/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 641ms/step - accuracy: 0.9997 - loss: 0.2472
Epoch 127: val_loss improved from 0.25504 to 0.25115, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 821ms/step - accuracy: 0.9997 - loss: 0.2472 - val_accuracy: 0.9961 - val_loss: 0.2512 - learning_rate: 5.0000e-04
Epoch 128/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 644ms/step - accuracy: 0.9999 - loss: 0.2408
Epoch 128: val_loss improved from 0.25115 to 0.24463, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 883ms/step - accuracy: 0.9999 - loss: 0.2408 - val_accuracy: 0.9987 - val_loss: 0.2446 - learning_rate: 5.0000e-04
Epoch 129/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 638ms/step - accuracy: 0.9989 - loss: 0.2403
Epoch 129: val_loss improved from 0.24463 to 0.24304, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 883ms/step - accuracy: 0.9989 - loss: 0.2403 - val_accuracy: 0.9974 - val_loss: 0.2430 - learning_rate: 5.0000e-04
Epoch 130/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9983 - loss: 0.2326
Epoch 130: val_loss did not improve from 0.24304
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 746ms/step - accuracy: 0.9983 - loss: 0.2326 - val_accuracy: 0.9948 - val_loss: 0.2490 - learning_rate: 5.0000e-04
Epoch 131/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9983 - loss: 0.2274
Epoch 131: val_loss improved from 0.24304 to 0.23956, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 889ms/step - accuracy: 0.9983 - loss: 0.2273 - val_accuracy: 0.9948 - val_loss: 0.2396 - learning_rate: 5.0000e-04
Epoch 132/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 645ms/step - accuracy: 0.9999 - loss: 0.2200
Epoch 132: val_loss improved from 0.23956 to 0.23162, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 887ms/step - accuracy: 0.9998 - loss: 0.2201 - val_accuracy: 0.9961 - val_loss: 0.2316 - learning_rate: 5.0000e-04
Epoch 133/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 640ms/step - accuracy: 0.9996 - loss: 0.2153
Epoch 133: val_loss improved from 0.23162 to 0.22561, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 20s 825ms/step - accuracy: 0.9996 - loss: 0.2153 - val_accuracy: 0.9961 - val_loss: 0.2256 - learning_rate: 5.0000e-04
Epoch 134/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 651ms/step - accuracy: 0.9981 - loss: 0.2159
Epoch 134: val_loss improved from 0.22561 to 0.21652, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 899ms/step - accuracy: 0.9981 - loss: 0.2158 - val_accuracy: 0.9974 - val_loss: 0.2165 - learning_rate: 5.0000e-04
Epoch 135/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 647ms/step - accuracy: 0.9989 - loss: 0.2073
Epoch 135: val_loss did not improve from 0.21652
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 752ms/step - accuracy: 0.9989 - loss: 0.2073 - val_accuracy: 0.9961 - val_loss: 0.2170 - learning_rate: 5.0000e-04
Epoch 136/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 631ms/step - accuracy: 0.9991 - loss: 0.2031
Epoch 136: val_loss improved from 0.21652 to 0.20744, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 889ms/step - accuracy: 0.9990 - loss: 0.2031 - val_accuracy: 0.9974 - val_loss: 0.2074 - learning_rate: 5.0000e-04
Epoch 137/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 635ms/step - accuracy: 0.9980 - loss: 0.1978
Epoch 137: val_loss improved from 0.20744 to 0.20264, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 881ms/step - accuracy: 0.9980 - loss: 0.1978 - val_accuracy: 0.9961 - val_loss: 0.2026 - learning_rate: 5.0000e-04
Epoch 138/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 639ms/step - accuracy: 0.9992 - loss: 0.1924
Epoch 138: val_loss improved from 0.20264 to 0.19639, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 871ms/step - accuracy: 0.9992 - loss: 0.1924 - val_accuracy: 0.9974 - val_loss: 0.1964 - learning_rate: 5.0000e-04
Epoch 139/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 647ms/step - accuracy: 0.9993 - loss: 0.1882
Epoch 139: val_loss improved from 0.19639 to 0.19403, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 893ms/step - accuracy: 0.9993 - loss: 0.1882 - val_accuracy: 0.9974 - val_loss: 0.1940 - learning_rate: 5.0000e-04
Epoch 140/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 641ms/step - accuracy: 0.9987 - loss: 0.1843
Epoch 140: val_loss improved from 0.19403 to 0.19324, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 885ms/step - accuracy: 0.9987 - loss: 0.1843 - val_accuracy: 0.9974 - val_loss: 0.1932 - learning_rate: 5.0000e-04
Epoch 141/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9998 - loss: 0.1785
Epoch 141: val_loss improved from 0.19324 to 0.19079, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 886ms/step - accuracy: 0.9998 - loss: 0.1785 - val_accuracy: 0.9961 - val_loss: 0.1908 - learning_rate: 5.0000e-04
Epoch 142/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 640ms/step - accuracy: 0.9987 - loss: 0.1760
Epoch 142: val_loss improved from 0.19079 to 0.18464, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 880ms/step - accuracy: 0.9987 - loss: 0.1759 - val_accuracy: 0.9974 - val_loss: 0.1846 - learning_rate: 5.0000e-04
Epoch 143/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 645ms/step - accuracy: 0.9993 - loss: 0.1711
Epoch 143: val_loss improved from 0.18464 to 0.18112, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 22s 915ms/step - accuracy: 0.9993 - loss: 0.1711 - val_accuracy: 0.9961 - val_loss: 0.1811 - learning_rate: 5.0000e-04
Epoch 144/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9989 - loss: 0.1678
Epoch 144: val_loss improved from 0.18112 to 0.17375, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 878ms/step - accuracy: 0.9989 - loss: 0.1678 - val_accuracy: 0.9987 - val_loss: 0.1738 - learning_rate: 5.0000e-04
Epoch 145/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 645ms/step - accuracy: 0.9996 - loss: 0.1624
Epoch 145: val_loss improved from 0.17375 to 0.16940, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 885ms/step - accuracy: 0.9996 - loss: 0.1624 - val_accuracy: 0.9974 - val_loss: 0.1694 - learning_rate: 5.0000e-04
Epoch 146/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 643ms/step - accuracy: 0.9996 - loss: 0.1587
Epoch 146: val_loss improved from 0.16940 to 0.16890, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 23s 967ms/step - accuracy: 0.9996 - loss: 0.1587 - val_accuracy: 0.9961 - val_loss: 0.1689 - learning_rate: 5.0000e-04
Epoch 147/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 640ms/step - accuracy: 0.9996 - loss: 0.1542
Epoch 147: val_loss improved from 0.16890 to 0.16480, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 878ms/step - accuracy: 0.9996 - loss: 0.1542 - val_accuracy: 0.9961 - val_loss: 0.1648 - learning_rate: 5.0000e-04
Epoch 148/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 640ms/step - accuracy: 0.9998 - loss: 0.1502
Epoch 148: val_loss improved from 0.16480 to 0.15907, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 882ms/step - accuracy: 0.9998 - loss: 0.1502 - val_accuracy: 0.9961 - val_loss: 0.1591 - learning_rate: 5.0000e-04
Epoch 149/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 649ms/step - accuracy: 0.9995 - loss: 0.1479
Epoch 149: val_loss did not improve from 0.15907
24/24 ━━━━━━━━━━━━━━━━━━━━ 18s 755ms/step - accuracy: 0.9995 - loss: 0.1479 - val_accuracy: 0.9961 - val_loss: 0.1611 - learning_rate: 5.0000e-04
Epoch 150/150
24/24 ━━━━━━━━━━━━━━━━━━━━ 0s 631ms/step - accuracy: 0.9989 - loss: 0.1454
Epoch 150: val_loss improved from 0.15907 to 0.15092, saving model to /content/drive/MyDrive/best_cauliflower_model.h5
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
24/24 ━━━━━━━━━━━━━━━━━━━━ 21s 882ms/step - accuracy: 0.9989 - loss: 0.1455 - val_accuracy: 0.9974 - val_loss: 0.1509 - learning_rate: 5.0000e-04
Restoring model weights from the end of the best epoch: 150.

✓ Training completed!
Training&Validation Test
print('\n' + '=' * 80)
print('POST-TRAINING ANALYSIS')
print('=' * 80)

# Check final metrics
final_train_loss = history.history['loss'][-1]
final_train_acc = history.history['accuracy'][-1]
final_val_loss = history.history['val_loss'][-1]
final_val_acc = history.history['val_accuracy'][-1]

print(f'\nFinal Training   - Loss: {final_train_loss:.4f}, Accuracy: {final_train_acc:.4f}')
print(f'Final Validation - Loss: {final_val_loss:.4f}, Accuracy: {final_val_acc:.4f}')

# Find best epoch
best_epoch = np.argmin(history.history['val_loss']) + 1
best_val_loss = np.min(history.history['val_loss'])
best_val_acc = history.history['val_accuracy'][best_epoch - 1]

print(f'\nBest Epoch: {best_epoch}')
print(f'  Validation Loss: {best_val_loss:.4f}')
print(f'  Validation Accuracy: {best_val_acc:.4f}')

# Quick sanity check on a few predictions
print('\n🔍 Quick Prediction Check (first 10 validation samples):')
val_batch, val_labels_batch = next(iter(valid_ds))
val_predictions = model.predict(val_batch[:10])
val_pred_classes = np.argmax(val_predictions, axis=1)
val_class_names = [classes[i] for i in val_pred_classes]
print('Predicted classes:', val_class_names)

unique_preds = np.unique(val_pred_classes)
if len(unique_preds) > 1:
    print('✅ GOOD: Model is predicting MULTIPLE classes (not just Healthy)!')
else:
    print('⚠️ WARNING: Model still predicting only one class. Check training logs.')

print('=' * 80)
Out
================================================================================
POST-TRAINING ANALYSIS
================================================================================

Final Training   - Loss: 0.1462, Accuracy: 0.9983
Final Validation - Loss: 0.1509, Accuracy: 0.9974

Best Epoch: 150
  Validation Loss: 0.1509
  Validation Accuracy: 0.9974

🔍 Quick Prediction Check (first 10 validation samples):
1/1 ━━━━━━━━━━━━━━━━━━━━ 36s 36s/step
Predicted classes: ['Healthy', 'Black Rot', 'Alternaria Leaf Spot', 'Alternaria Leaf Spot', 'Healthy', 'Downy Mildew', 'Bacterial Soft Rot', 'Black Rot', 'Alternaria Leaf Spot', 'Downy Mildew']
✅ GOOD: Model is predicting MULTIPLE classes (not just Healthy)!
================================================================================
Define a function to plot the training data
def tr_plot(tr_data, start_epoch):
    #Plot the training and validation data
    tacc=tr_data.history['accuracy']
    tloss=tr_data.history['loss']
    vacc=tr_data.history['val_accuracy']
    vloss=tr_data.history['val_loss']
    Epoch_count=len(tacc)+ start_epoch
    Epochs=[]
    for i in range (start_epoch ,Epoch_count):
        Epochs.append(i+1)
    index_loss=np.argmin(vloss)#  this is the epoch with the lowest validation loss
    val_lowest=vloss[index_loss]
    index_acc=np.argmax(vacc)
    acc_highest=vacc[index_acc]
    plt.style.use('fivethirtyeight')
    sc_label='best epoch= '+ str(index_loss+1 +start_epoch)
    vc_label='best epoch= '+ str(index_acc + 1+ start_epoch)
    fig,axes=plt.subplots(nrows=1, ncols=2, figsize=(20,8))
    axes[0].plot(Epochs,tloss, 'r', label='Training loss')
    axes[0].plot(Epochs,vloss,'g',label='Validation loss' )
    axes[0].scatter(index_loss+1 +start_epoch,val_lowest, s=150, c= 'blue', label=sc_label)
    axes[0].set_title('Training and Validation Loss')
    axes[0].set_xlabel('Epochs')
    axes[0].set_ylabel('Loss')
    axes[0].legend()
    axes[1].plot (Epochs,tacc,'r',label= 'Training Accuracy')
    axes[1].plot (Epochs,vacc,'g',label= 'Validation Accuracy')
    axes[1].scatter(index_acc+1 +start_epoch,acc_highest, s=150, c= 'blue', label=vc_label)
    axes[1].set_title('Training and Validation Accuracy')
    axes[1].set_xlabel('Epochs')
    axes[1].set_ylabel('Accuracy')
    axes[1].legend()
    plt.tight_layout
    plt.show()

tr_plot(history,0)
Out
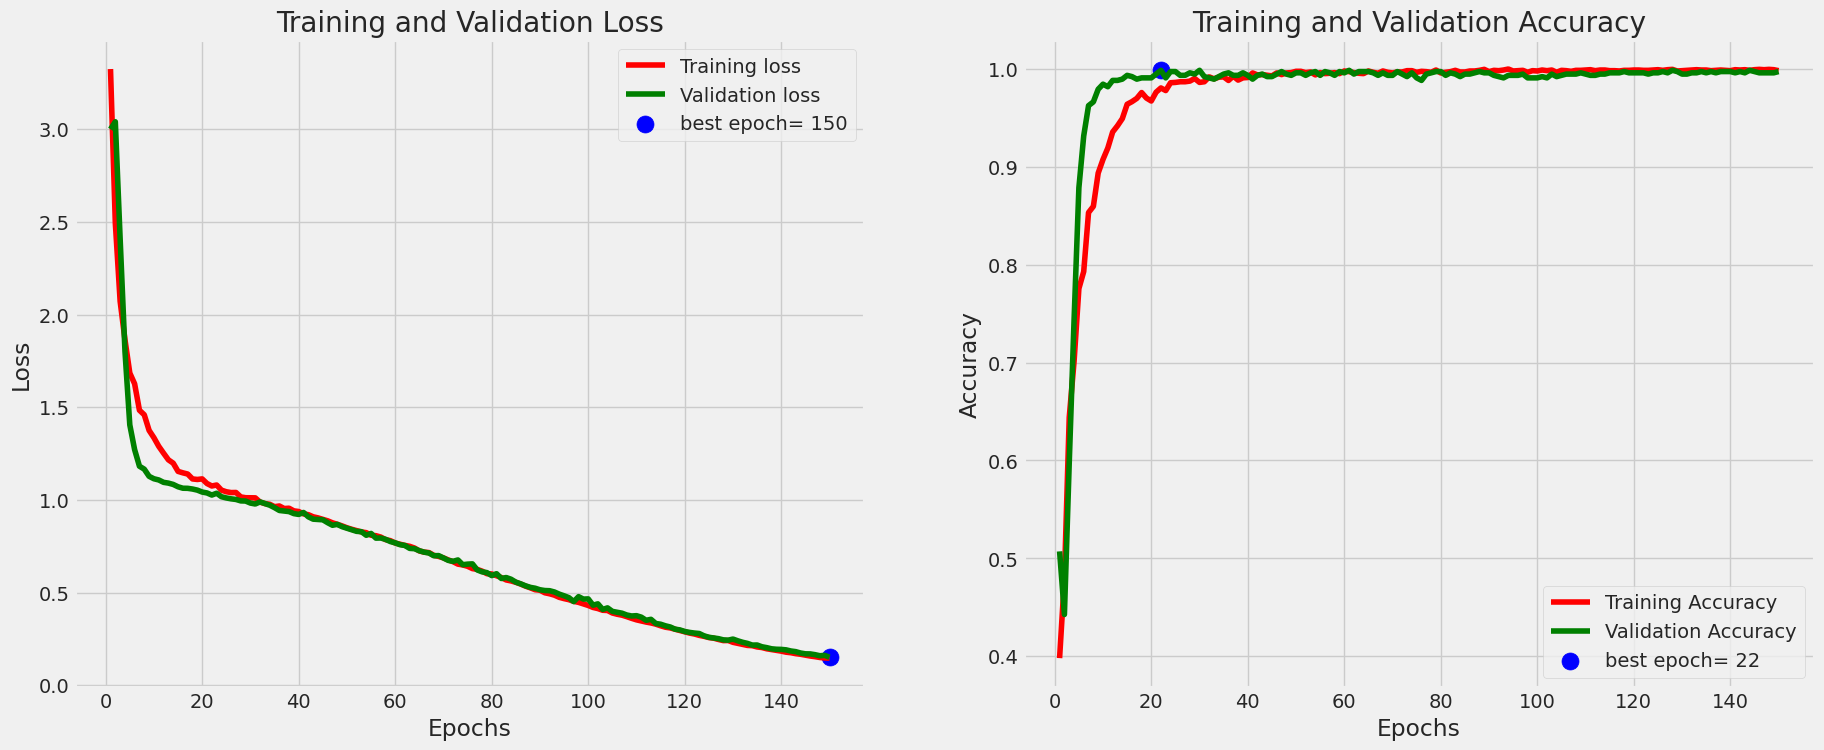
Make Predictions on the test set
Define a function which takes in a test generator and an integer test_steps
and generates predictions on the test set including a confusion matric
and a classification report
def predictor_from_df(test_df, test_ds):
    y_true = test_df['labels'].map(class_to_idx).values
    filepaths = test_df['filepaths'].values
    class_names_local = class_names
    errors = 0
    preds = model.predict(test_ds, verbose=1)
    pred_indices = np.argmax(preds, axis=1)
    for i, (p, t) in enumerate(zip(pred_indices, y_true)):
        if p != t:
            errors += 1
            print('file ', filepaths[i], ' was an error')

    acc = (1 - errors/len(y_true)) * 100
    print(f'there were {errors} errors in {len(y_true)} tests for an accuracy of {acc:6.2f}')

    cm = confusion_matrix(y_true, pred_indices)
    plt.figure(figsize=(12, 8))
    sns.heatmap(cm, annot=True, vmin=0, fmt='g', cmap='Blues', cbar=False)
    plt.xticks(np.arange(class_count)+.5, class_names_local, rotation=90)
    plt.yticks(np.arange(class_count)+.5, class_names_local, rotation=0)
    plt.xlabel("Predicted")
    plt.ylabel("Actual")
    plt.title("Confusion Matrix")
    plt.show()

    clr = classification_report(y_true, pred_indices, target_names=class_names_local, digits=4)
    print("Classification Report:\n----------------------\n", clr)
    return errors, len(y_true)

errors, tests = predictor_from_df(test_df, test_ds)
Out
7/7 ━━━━━━━━━━━━━━━━━━━━ 50s 6s/step
file  /content/cauliflower_training/cali/Alternaria Leaf Spot/alternaria_leaf_spot_0064.jpg  was an error
file  /content/cauliflower_training/cali/Downy Mildew/downy_mildew_0985.jpg  was an error
file  /content/cauliflower_training/cali/Alternaria Leaf Spot/alternaria_leaf_spot_0002.jpg  was an error
there were 3 errors in 776 tests for an accuracy of  99.61
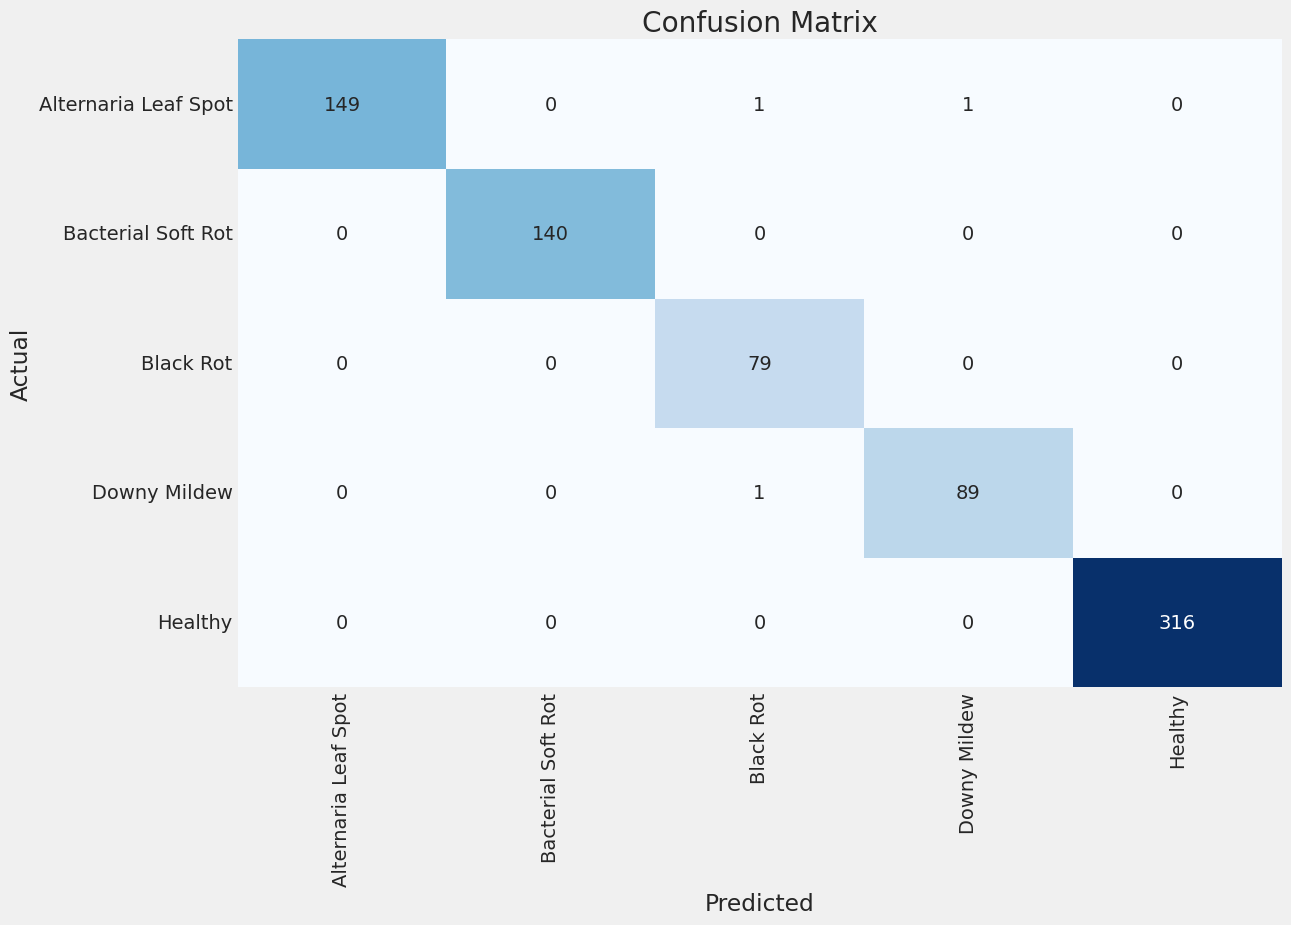
Classification Report:
----------------------
                       precision    recall  f1-score   support

Alternaria Leaf Spot     1.0000    0.9868    0.9933       151
  Bacterial Soft Rot     1.0000    1.0000    1.0000       140
           Black Rot     0.9753    1.0000    0.9875        79
        Downy Mildew     0.9889    0.9889    0.9889        90
             Healthy     1.0000    1.0000    1.0000       316

            accuracy                         0.9961       776
           macro avg     0.9928    0.9951    0.9939       776
        weighted avg     0.9962    0.9961    0.9961       776
Save the model
subject='nuts'
acc=str(( 1-errors/tests) * 100)
index=acc.rfind('.')
acc=acc[:index + 3]
save_id= subject + '_' + str(acc) + '.h5'
model_save_loc=os.path.join(working_dir, save_id)
model.save(model_save_loc)
print ('model was saved as ' , model_save_loc )
Out
WARNING:absl:You are saving your model as an HDF5 file via `model.save()` or `keras.saving.save_model(model)`. This file format is considered legacy. We recommend using instead the native Keras format, e.g. `model.save('my_model.keras')` or `keras.saving.save_model(model, 'my_model.keras')`.
model was saved as  ./nuts_99.61.h5